A canonical URL is the representative or preferred version of a webpage that a search engine selects to index from a set of duplicate or near-duplicate pages. The selection process, canonicalization, lets search engines deduplicate similar URLs and show only the most relevant version in search results. Canonical URLs are declared with the rel="canonical" link element, which tells search engines which URL to treat as canonical when several candidates exist, and Google weighs added factors such as redirects, sitemap inclusion, and internal linking patterns when making the choice.
Canonicalization differs from redirects in that the canonical and the duplicate URLs both stay accessible to users, while a redirect removes the duplicate from user access and sends visitors straight to the target URL. Two main types of canonical URLs exist: self-referencing canonicals, where a page's rel="canonical" points to its own URL, and cross-domain canonicals, where a syndicated page points to the original article on another domain. Canonical URLs matter for SEO because they consolidate ranking signals and prevent duplicate-content indexing, which clutters search results and wastes crawl budget.
URL variations that need canonicalization include differences in protocol (HTTP versus HTTPS), host (www versus non-www), trailing slashes, URL parameters, pagination, and syndication. Best practices for canonical tags cover using absolute URLs, one canonical per page, an indexable target, and placement in the document's <head>. The mistakes to avoid include canonical tags pointing at redirected or noindexed URLs, canonicals on non-duplicate content, and canonical chains or loops. Canonical URLs get verified in Google Search Console through the URL Inspection tool, which shows the "user-declared canonical" next to the "Google-selected canonical."
SEO agencies implement canonical URL fixes by running full crawl audits to find issues, configuring CMS settings for correct canonical output, and applying per-page overrides where needed. Agencies monitor canonical signals through scheduled site audits and Search Console integrations, putting high-traffic and revenue-generating pages first. Long-term support runs on quarterly reviews and proactive updates that keep canonical governance consistent, so ranking signals stay consolidated and the site's indexing footprint stays clean.
What is a canonical URL in SEO?
A canonical URL in SEO is the preferred version of a webpage that a search engine selects from a group of duplicate or similar pages. The canonical URL acts as the "master copy" into which ranking signals, from link equity to PageRank, get consolidated. Canonical URLs keep search engines from indexing multiple versions of the same content, which would dilute ranking potential and confuse users.
In practice, a canonical URL tells search engines to treat one URL as the authoritative source. The signal matters most when a site generates multiple URLs for the same content through protocol variations (HTTP vs. HTTPS), domain differences (www vs. non-www), tracking parameters, or device-targeted versions. Designating a canonical URL concentrates authority and relevance signals into one preferred page and keeps the SEO strategy intact.
The canonical URL stands apart from its duplicates: the canonical is the authoritative version, while duplicates are the URL permutations and content copies that exist across the site or the wider web.
How does a canonical URL differ from a duplicate URL?
A canonical URL differs from a duplicate URL as the indexed version differs from its alternatives: the canonical is the preferred version search engines index, while a duplicate URL is any alternative address serving the same or similar content. Websites generate duplicate URLs for many reasons, including regional or device-specific versions, syndicated content, and URL parameter variations. Regional targeting may produce separate URLs for USA and UK markets, while device-targeted rendering can create URLs for mobile and desktop views.
Duplicates arise from protocol differences like HTTP versus HTTPS and domain variants such as www versus non-www as well. E-commerce sites meet duplicates through faceted navigation, where filtering by color or size spawns a URL per combination, and marketing campaigns add more when UTM parameters and tracking codes wrap the same landing page in multiple addresses. Canonical URLs resolve the indexing ambiguity every one of those scenarios creates.
What is a canonical tag in HTML?
A canonical tag in HTML is a <link> element that specifies the preferred URL of a webpage among duplicates. The syntax is <link rel="canonical" href="https://www.example.com/preferred-page">, placed within the <head> section of the HTML document. The tag requires an absolute URL, so search engines like Google read exactly which version of a page counts as the authoritative copy.
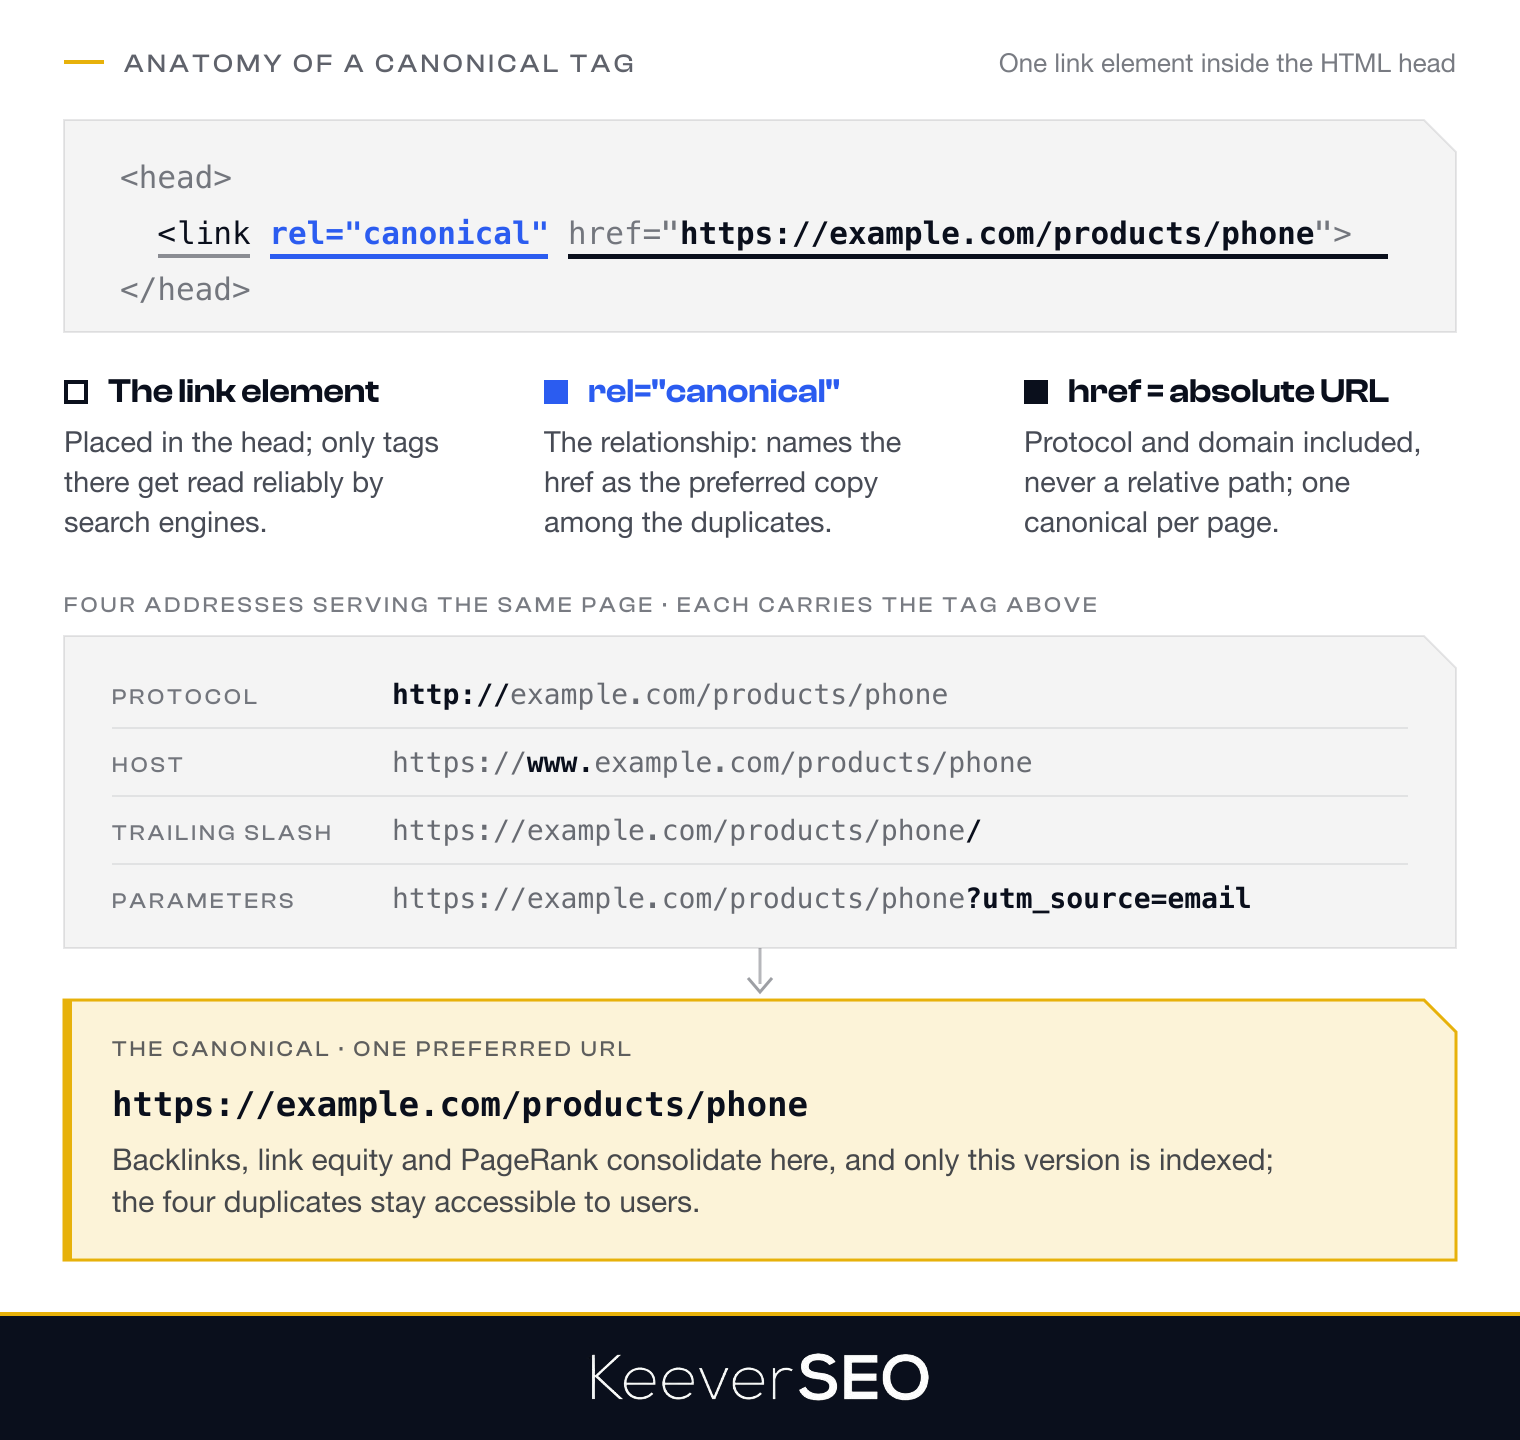
The canonical tag works as a strong hint to search engines, marking which URL should receive credit when multiple pages carry similar content, and it anchors the wider mechanism through which canonical URLs consolidate ranking signals and prevent duplicate-content issues.
How do canonical URLs work?
Canonical URLs work through a hierarchy of signals that guide search engines toward the preferred version of a page among duplicates. The strongest signal is the 301 redirect, which permanently moves one URL to another and consolidates all ranking signals. Next in strength comes the rel="canonical" tag, placed in the HTML <head> or sent via HTTP header, which names the preferred URL without removing access to the duplicates. Sitemap inclusion works as a weaker supporting signal, suggesting preferred URLs by listing them. The rel="canonical" HTTP header extends the mechanism to non-HTML files such as PDFs, which declare a canonical through the syntax Link: <url>; rel="canonical".
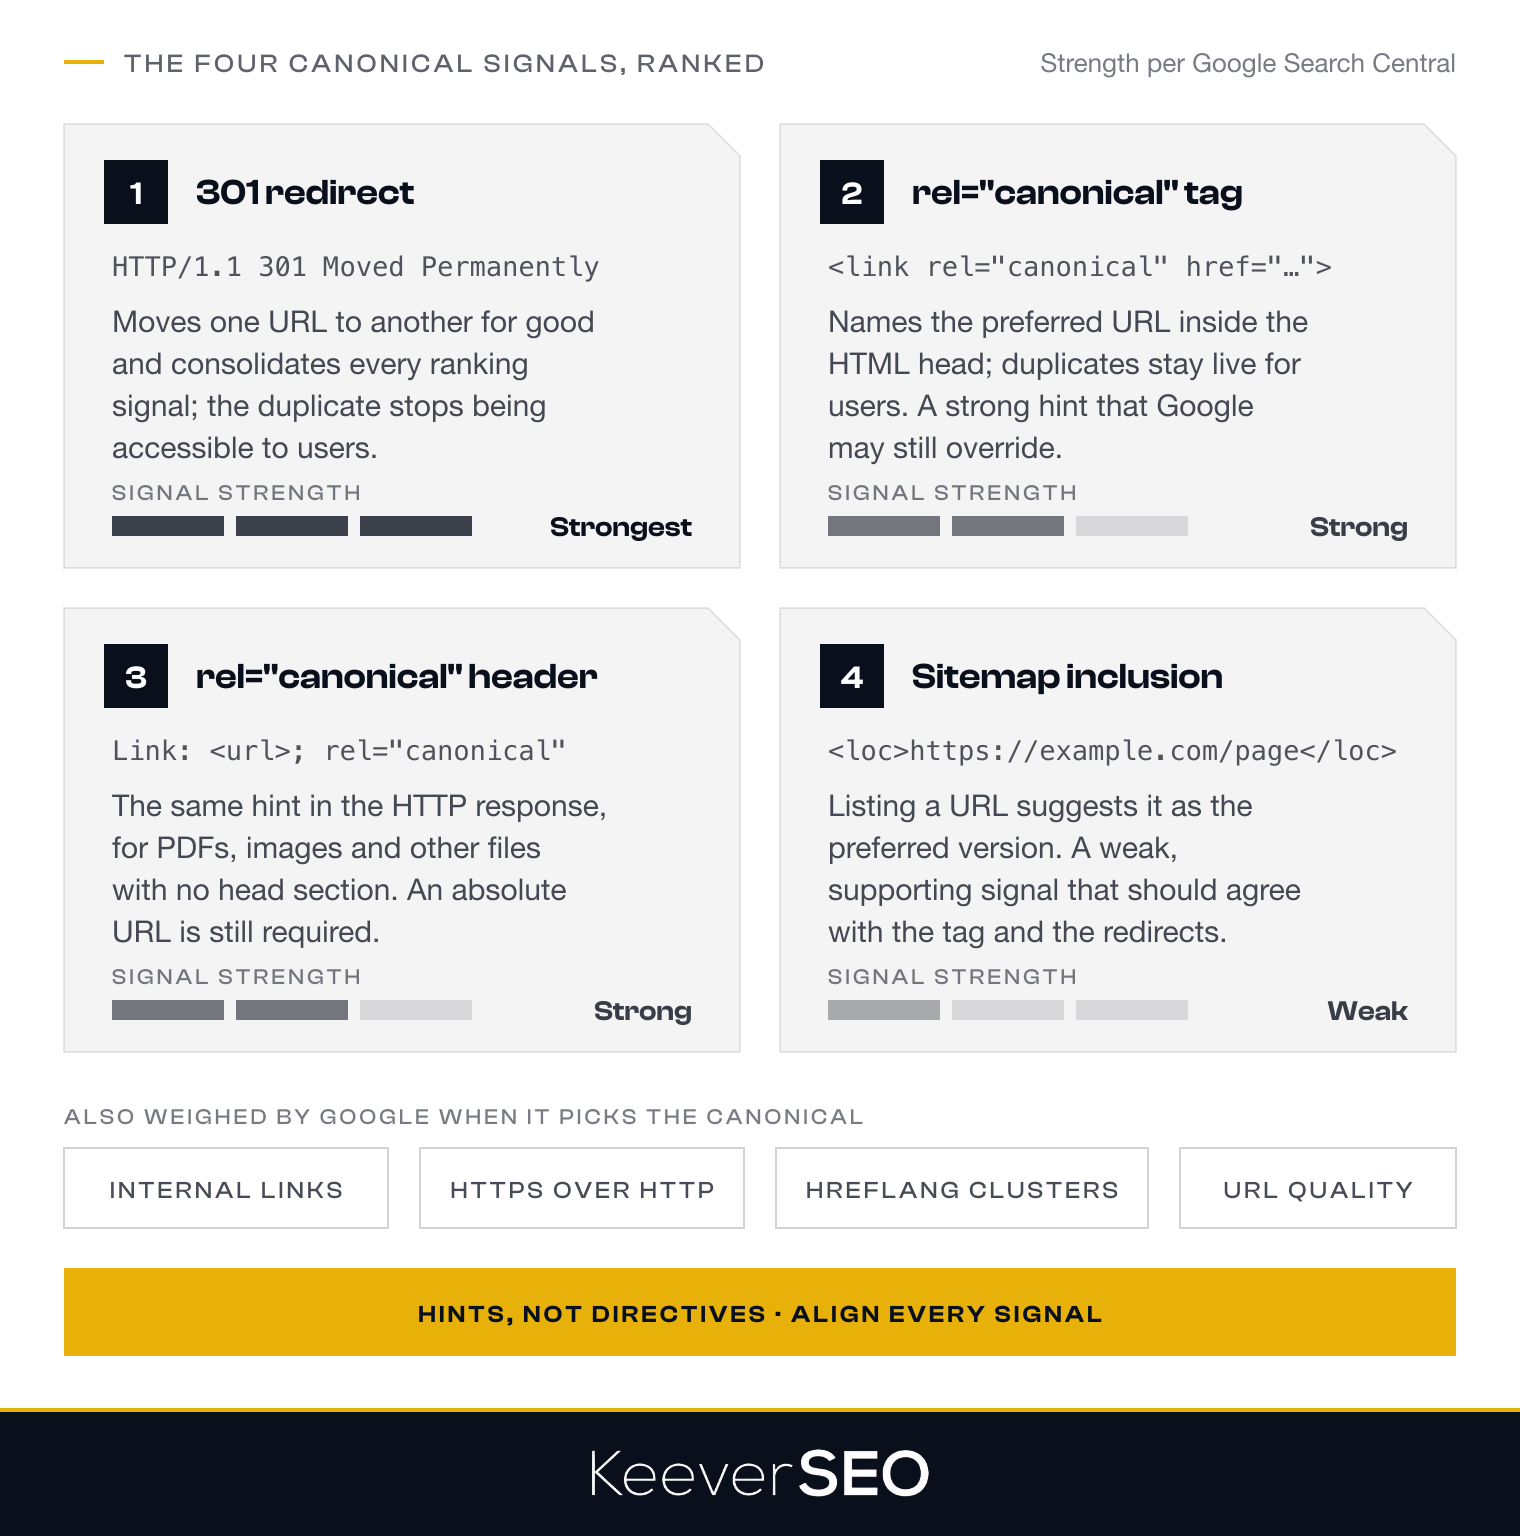
The signals serve as hints rather than directives, per Google Search Central's documentation "How to Specify a Canonical with rel="canonical" and Other Methods," which grades redirects and rel="canonical" annotations as strong signals and sitemap inclusion as a weak one: a webmaster can declare a canonical, and Google may still choose a different version based on signal consistency, internal links, HTTPS preference, and URL quality. The method-strength ordering, 301 redirect first, then rel="canonical", then sitemap inclusion, reflects how much control each signal exerts, and aligning every signal consistently raises the odds that the preferred canonical gets respected.
How does an HTML rel="canonical" tag signal a preferred URL?
An HTML rel="canonical" tag signals a preferred URL by handing search engines a strong hint about which version of a page to index and rank. The tag sits in the <head> section and uses the syntax <link rel="canonical" href="https://example.com/preferred-page">, telling search engines like Google which URL takes priority even when similar content exists elsewhere.
The rel="canonical" tag is a recommendation rather than a directive, so search engines may pick a different URL when other signals argue for a better choice. Every page should carry a self-referential canonical tag by default, pointing to itself, so unintended variants carrying tracking parameters or session IDs never get selected as canonical. Self-referencing keeps the signal clear, above all on sites where URL parameters keep generating duplicate content.
How can rel="canonical" HTTP headers signal a preferred URL?
rel="canonical" HTTP headers signal a preferred URL for non-HTML files, such as PDFs and images, through the Link: <url>; rel="canonical" syntax in the server's HTTP response header. The header suits files that cannot carry HTML markup, letting them point at a canonical URL without a <head> section. The header works like the HTML canonical tag, naming which URL counts as canonical so search engines consolidate ranking signals onto it. The absolute-URL requirement still applies, and the header stays a hint rather than a directive, so search engines may pick a different canonical when redirects or internal linking argue otherwise.
How does Google choose a canonical URL?
Google chooses a canonical URL by weighing multiple signals to find the most representative version among a set of duplicates. The primary factors are redirect signals, rel="canonical" link annotations, and sitemap inclusion. Google reads internal linking patterns, HTTPS preference over HTTP, and hreflang cluster consistency alongside, and the URL's own quality, from cleanliness to structure, feeds the decision. Google treats the declared canonical as a strong hint rather than a directive, keeping the right to override it when other signals point to a page that serves users better; Google's canonicalization documentation states the engine identifies which version of the URL is objectively the best to show users in Search.
How do canonical URLs differ from redirects?
Canonical URLs differ from redirects in user access, signal consolidation, use case, and reversibility, as the table below lays out.
| Aspect | Canonical Tag | 301 Redirect |
|---|---|---|
| User access to the duplicate URL | Both URLs remain accessible; users can visit either version | Duplicate URL automatically forwards users to the preferred URL |
| Signal/PageRank consolidation | Consolidates ranking signals to the canonical URL as a hint | Consolidates ranking signals definitively to the target URL |
| Typical use case | Near-duplicate pages that must both stay live (product filters, tracking parameters, syndicated content) | Permanent URL moves, site migrations, or true consolidation where the old URL should not be accessed |
| Reversibility | Reversible by removing or changing the tag | Requires a server configuration change; more involved to reverse |
The distinctions decide when a redirect beats a canonical tag: whenever the duplicate URL should stop being accessible, or the content is being permanently consolidated under a single address.
When should redirects be used instead of canonical tags?
Redirects should be used instead of canonical tags when a URL needs to move permanently or disappear from user access. A 301 redirect fits transitions from HTTP to HTTPS, mergers of duplicate content, and the retirement of outdated pages, transferring traffic, link equity, and ranking signals to the new URL while removing the old one from access and indexing. Canonical tags fit the opposite case: near-duplicate content that must stay live, from paginated series to regional variants, where the preferred version gets named without cutting access to the others.
What are the types of canonical URLs?
The types of canonical URLs are listed below:
- Self-referencing canonical URLs: the page points to itself as the preferred version, the default recommendation for all pages, which clarifies the preferred URL and protects against parameter variants.
- Cross-domain canonical URLs: a syndicated or republished page on another domain points to the original source, so the original publisher keeps the ranking credit.
- Protocol canonical URLs: pages accessible over HTTP and HTTPS canonicalize to the HTTPS version, marking the secure protocol as preferred.
- Domain variant canonical URLs: the canonical resolves www versus non-www duplicates, naming the version that matches the site's preferred domain structure.
- Parameter-based canonical URLs: pages carrying tracking codes, session IDs, or filter parameters canonicalize to the clean base URL, preventing ranking-signal fragmentation.
- Paginated canonical URLs: paginated pages either self-reference or point at a "view all" page; self-referencing wins in most cases because each page can rank for its own content.
- Filtered and faceted navigation canonical URLs: filtered product listings canonicalize to the unfiltered category page, unless a filtered view earns separate indexing as a distinct landing page.
Of the seven, the self-referencing canonical carries the widest duty, serving as baseline protection for every page on the site.
What is a self-referencing canonical URL?
A self-referencing canonical URL is a canonical tag that points to the page's own URL, declaring the page itself the preferred version. Self-referencing canonicals are the recommended default for all indexable pages, giving search engines an explicit signal about the master copy even when no duplicates exist. Deployed site-wide, self-referencing canonicals form a protective layer against accidental duplication: when URL parameters, tracking codes, or session IDs get appended, the canonical keeps the clean base URL treated as authoritative.
Self-referencing canonical tags make canonicalization predictable and shrink the ambiguity in how Google selects the canonical. Rather than leaving the choice to the algorithm, the tag hands the site owner control over which version gets indexed, consolidating ranking signals onto the intended URL and stopping parameter variants from fragmenting page authority.
What is a cross-domain canonical URL?
A cross-domain canonical URL is a canonical tag that names the original source of content appearing on multiple domains. The tag belongs on the duplicate page, pointing to the original URL on the other domain through <link rel="canonical" href="https://originaldomain.com/original-article">, which tells search engines like Google to treat the original domain as authoritative, consolidate the ranking signals there, and keep the duplicate from outranking the source.
Cross-domain canonical tags serve publishers who syndicate content for reach while protecting the SEO value of the original. The tags count as strong hints rather than strict directives, and they succeed in steering search engines toward the original in most cases, so the first publisher keeps the primary SEO benefit even as the content spreads.
Why do canonical URLs matter for SEO?
Canonical URLs matter for SEO because they consolidate ranking signals and prevent duplicate-content indexing. A designated canonical directs search engines to treat one version of a page as primary, so backlinks and ranking signals accrue to the preferred version and raise its visibility in search results. Without canonicalization, search engines can index several versions of the same content, diluting ranking potential and producing duplicate-content problems.
Canonical URLs keep the index clean and efficient too, sparing search engines the cost of storing duplicate pages. The stakes climb for large websites with many similar pages, such as e-commerce sites full of product variants, where proper canonicalization concentrates crawl effort on the pages that count and protects the crawl budget.
How do canonical URLs consolidate ranking signals and prevent duplicate-content indexing issues?
Canonical URLs consolidate ranking signals by directing all link equity, PageRank included, to a single preferred URL. When multiple pages share identical or similar content, backlinks and internal links scatter across the duplicates and fragment the authority each URL accumulates. Declaring a canonical merges the scattered signals into one representative page, strengthening its ability to rank, and it instructs search engines to index only the canonical version, so users see the most complete and authoritative copy in results.
Canonical URLs improve crawl-budget efficiency alongside. Search engines that meet floods of duplicate pages spend crawl resources on redundant content, which delays the discovery and indexing of genuinely fresh pages, above all on large websites. Canonicalized duplicates let crawlers concentrate on the preferred URLs, putting the crawl budget to work on new, distinct content; Google's guide "Optimize your crawl budget" lists consolidating duplicate content among the core techniques for keeping crawling focused on the URLs that matter. Proper canonical tags help Google group duplicate pages and pick the most useful URL to serve, which supports link-equity consolidation and crawl-budget management at once.
Which URL variations need canonicalization?
The URL variations that need canonicalization are listed below:
- HTTP vs. HTTPS: URLs reachable over both protocols canonicalize to the HTTPS version.
- www vs. non-www: one host becomes canonical so ranking signals never split.
- Trailing slash vs. no trailing slash: one convention wins, keeping the pair from indexing as duplicates.
- Query parameters: URLs carrying tracking or session parameters point to the clean canonical URL.
- Faceted filters: e-commerce filter combinations canonicalize to the main category pages.
- Pagination: paginated content follows a clear canonical strategy so similar pages never pile into the index.
- Syndication: content republished on other sites refers back to the original URL as the canonical source.
A site that handles all seven variation classes keeps its canonical signals clean across the whole URL inventory.
How should canonical URLs handle tracking parameters and ecommerce filters?
Canonical URLs should point tracking parameters and ecommerce filters at a clean base URL, so multiple near-identical versions of a page never enter the index. Tracking parameters like ?utm_source=, ?utm_medium=, and ?utm_campaign= serve marketing measurement without changing the content, while ecommerce filters like ?color=red or ?size=large spawn faceted URLs that show the same category with slight variations.
Each parameter-driven URL carries a canonical tag pointing back to the base URL: example.com/products/phone?utm_source=email&color=blue canonicalizes to example.com/products/phone. The pattern consolidates ranking signals onto the primary page, stops link equity from spreading across filter combinations, and gets Google indexing the most representative version of each category. Canonicalizing tracking and filter URLs to one clean base protects the index while the tracking and filtering keep working for users.
How do canonical URLs interact with hreflang for international pages?
Canonical URLs interact with hreflang by staying self-referencing within each language version. Every language variant of a page carries a canonical tag pointing to itself, never to a single master URL for all locales, so each localized page keeps its own canonical identity.
hreflang annotations then connect the pages to their equivalents in other languages and regions, letting search engines serve the right version by language preference and location. Google's canonical documentation instructs sites using hreflang to specify a canonical page in the same language, so canonical URLs must never fold all international variants into one URL: with French, German, and Spanish versions live, each canonicalizes to itself. Held to that rule, the hreflang cluster stays respected and every localized version stays indexable.
What are canonical tag best practices?
The canonical tag best practices are listed below:
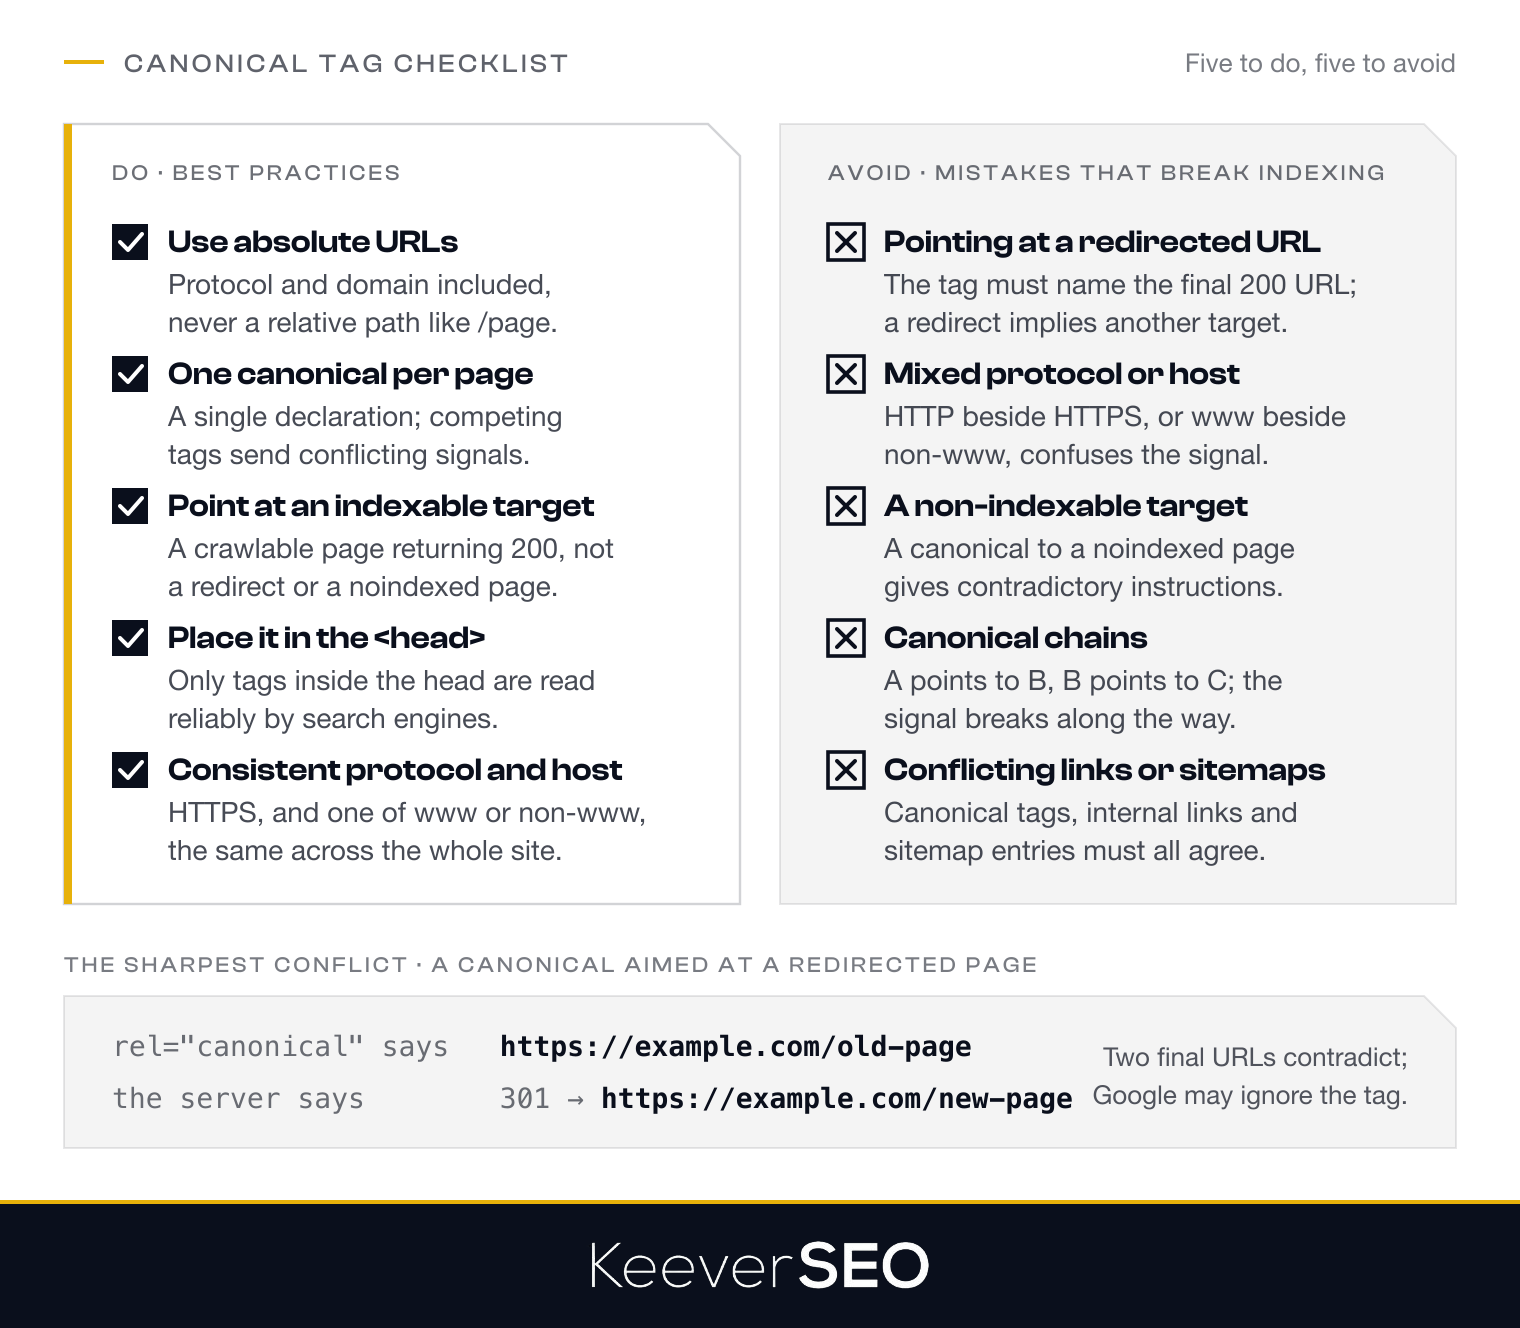
- Use absolute URLs: the full URL, protocol and domain included, removes ambiguity across environments.
- Specify one canonical per page: a single rel="canonical" per page prevents conflicting signals.
- Point to an indexable target: the canonical URL leads to a crawlable page returning a 200 status, never a redirect or a noindexed page.
- Place canonical tags in the
<head>section: only tags inside the<head>of the document get read reliably by search engines. - Use the correct protocol and host: the preferred protocol (HTTPS) and host (www or non-www) stay consistent so ranking signals consolidate.
What makes a valid canonical URL?
A valid canonical URL meets the technical criteria listed below:
- Absolute URL format: fully qualified, protocol and domain included (https://example.com/page), never a relative path.
- Resolvable and accessible: returns a 200 HTTP status code and stays reachable for search engine crawlers.
- Indexable target: not blocked by robots.txt, noindex meta tags, or X-Robots-Tag headers.
- Single canonical declaration: one canonical URL per page, with no competing declarations.
- Correct protocol: HTTPS wherever the site supports it, since search engines prefer secure versions.
- Consistent domain variant: www or non-www, matching the site's preferred configuration throughout.
- Final target URL: the canonical points straight at the final URL, never at a page that redirects onward.
What canonical tag mistakes cause indexing problems?
The canonical tag mistakes that cause indexing problems are listed below:
- Pointing to a redirected URL: the canonical must name the final 200-status URL, never an intermediate redirect.
- Incorrect protocol or host: mixing HTTP with HTTPS or www with non-www confuses the signal.
- Non-indexable target: a canonical pointing at a noindexed page sends contradictory instructions.
- Canonical chains: a canonical that points to another canonical, which points elsewhere, breaks the signal.
- Conflicting internal links or sitemaps: canonical tags, internal links, and sitemap entries must all agree.
Of the five mistakes, the canonical aimed at a redirected page produces the sharpest conflict.
Why are canonical tags pointing to redirected pages problematic?
Canonical tags pointing to redirected pages are problematic because they send search engines conflicting signals. A canonical tag should name the final URL returning a 200 HTTP status; when it points at a redirecting URL instead, the redirect implies a different final target and the messages contradict each other. The contradiction makes the search engine's canonical choice harder, and when the redirect target carries a noindex on top, the instructions tangle further, pushing Google to ignore the declared canonical and pick an alternative URL. Clear signals demand that canonical tags reference the live final URL while redirects carry the non-preferred variants.
How should XML sitemaps reinforce canonical URLs?
XML sitemaps should reinforce canonical URLs by listing only canonical URLs. A canonical-only sitemap keeps crawling and indexing pointed at the correct pages and lines up with the site's wider canonicalization strategy, adding a consistent signal beside rel="canonical" tags and redirects.
The sitemap ranks as a weaker signal than rel="canonical" tags or 301 redirects, yet it still plays a supporting role: sitemap inclusion is one of the factors weighed when the canonical gets chosen for a duplicate set. A sitemap kept to canonical URLs helps search engines spend crawl budget on the pages meant for indexing rather than on duplicate variants.
How are canonical URLs checked in Google Search Console?
Canonical URLs are checked in Google Search Console with the URL Inspection tool, which shows the "user-declared canonical" and the "Google-selected canonical" for any indexed page. Matching values confirm the canonical signal works; diverging values mean Google overrode the declared preference on the strength of other signals, from redirects to sitemap entries.
The Page Indexing report widens the view across the site, listing pages where Google chose a different canonical than the one declared. Patterns like "Duplicate, Google chose different canonical than user" point to systematic problems, and the fix starts with checking internal signals, redirects and internal links included, then requesting re-indexing after corrections.
Steady monitoring in Google Search Console keeps the site's canonical strategy aligned with Google's actual indexing decisions, stopping duplicates from splitting ranking signals. The single-page check then scales up into a site-wide canonical audit.
How are canonical tags audited across a website?
Canonical tags are audited across a website through a bulk crawl that checks every page's declaration. SEO site-audit tools like Semrush Site Audit and Screaming Frog inspect each page's canonical against its actual URL and indexability status, surfacing missing canonicals, multiple canonicals, and canonicals aimed at non-indexable targets.
The audit checks CMS-generated canonicals for consistency next, verifying template-level output across page types, from product pages to blog posts, and flagging where manual overrides introduced errors. A thorough audit marks canonical chains, loops, and conflicts, above all where user-declared canonicals differ from the ones search engines selected. Exporting crawl results and segmenting them by URL pattern puts the fixes in priority order, starting with the pages where errors threaten indexing or signal consolidation.
How do SEO agencies implement canonical URL fixes?
SEO agencies implement canonical URL fixes by configuring the CMS to output correct canonical tags consistently across every page. Platforms like WordPress, Shopify, and Magento get set to generate self-referencing canonicals by default, with protocol, domain preference, and trailing-slash conventions applied site-wide.
Where CMS defaults produce wrong canonicals, agencies apply per-page overrides. Filtered product listings and parameter-heavy URLs need the manual treatment most, with each override pointing the canonical at the correct version. Overrides stay aligned with the site's URL structure and cut the conflicts that duplicate templates and syndicated versions create.
How do SEO agencies check CMS-generated canonical tags?
SEO agencies check CMS-generated canonical tags by examining the automatic output of platforms like WordPress, Shopify, and Magento. In WordPress, plugins such as Yoast SEO generate canonical tags for pages and posts, and the check inspects the page source to confirm each tag points at the right URL. Shopify themes emit self-referencing canonicals through the {{ canonical_url }} liquid tag, confirmed by checking the HTML output on product and collection pages. In Magento, the check covers the built-in canonical settings for product and category pages plus any custom layout code behind CMS page canonicals.
Verification pairs automated tools with manual checks, holding every tag to the best practices: absolute URLs, correct protocol, indexable targets. Where a CMS default proves wrong, the adjustment moves to the individual page.
How can SEO agencies adjust canonical tags on individual pages?
SEO Agency In USA adjusts canonical tags on individual pages through manual overrides wherever the CMS default is wrong. The override applies when a page's built-in canonical points at the wrong version while the page itself must stay indexable. The agency edits the page's HTML template directly or sets the correct canonical through SEO plugin fields, so each page declares exactly the version that should count as canonical within the site's broader structure. Every override gets verified: the target URL returns a 200 status, matches the correct protocol, and creates no conflict with hreflang annotations.
How do SEO agencies monitor canonical URL signals?
SEO Agency In USA monitors canonical URL signals through a structured, ongoing process that keeps canonical tags working and Google aligned with the site's preferences. The cadence runs monthly for most sites and weekly for large e-commerce platforms and high-traffic sites whose URL structures change fast.
The core of the monitoring tracks divergence between user-declared and Google-selected canonicals. The SEO company reads Google Search Console's URL Inspection tool and Page Indexing reports to catch each override, since an override signals technical trouble: conflicting signals, canonical chains, or low-quality targets. Detected divergence triggers a root-cause investigation covering competing signals like redirects and inconsistent internal linking.
Automated site-audit tools, Semrush Site Audit and Screaming Frog among them, watch canonical tag health at scale, flagging loops, chains, and missing canonicals. Search Console data combined with third-party crawl intelligence gives the agency a live view of canonical signal integrity, so issues get fixed before they touch indexing or rankings.
When should an SEO agency prioritize canonical URL fixes?
An SEO agency should prioritize canonical URL fixes through a severity-and-impact triage that puts high-traffic and high-revenue pages first. Errors on those pages hit visibility and conversions directly, so pages with strong organic traffic and heavy link equity get fixed before anything else. Triage of that kind limits the immediate traffic and conversion loss that follows when multiple URLs compete for the same rankings on missing or conflicting canonical signals.
The framework weighs the type and scale of each issue as well. Widespread problems, protocol conflicts between HTTP and HTTPS or missing self-referencing canonicals across many pages, demand immediate work because they fragment ranking signals across the site. Single-page misconfigurations on low-traffic posts can wait their turn. A sharp divergence between user-declared and Google-selected canonicals in Search Console jumps the queue whenever Google overrides declarations on important pages, since the override means conflicting signals are eating into the site's authority consolidation.
How do SEO agencies support long-term canonical URLs?
SEO Agency In USA supports long-term canonical URL health through ongoing monitoring and governance. Regular audits catch canonical chains and loops as they appear and keep canonical signals aligned across the website, so duplicate signals never spread unnoticed.
Governance extends past the audits: client teams get trained on canonical best practices, alerts fire on serious canonical errors, and canonical checks sit inside the routine technical SEO workflow, so any drift gets corrected fast. The discipline keeps canonical URLs consolidating ranking signals and protecting crawl budgets year over year.
Held to that standard, canonical URLs stay a foundational layer of technical SEO, keeping the site optimized for indexing and ranking and carrying its organic performance over the long term.