A sitemap is a file that lists a website's important URLs, along with metadata that guides search engine discovery and crawling. The file works as a structured roadmap that lets search engines find and prioritize pages for crawling. The XML Sitemap Protocol is the standardized format behind it, and it communicates URLs, last modification dates, and page relationships to crawlers like Googlebot.
The main types of sitemaps are XML sitemaps for standard pages, HTML sitemaps for user navigation, image sitemaps, video sitemaps, news sitemaps, and sitemap index files that organize several sitemaps. XML sitemaps hold SEO value because they improve indexing efficiency, surface orphaned pages, and communicate content freshness, although they do not lift rankings on their own. Large websites, new sites with few backlinks, JavaScript-heavy sites, and media-rich sites gain the most from sitemaps, while small, well-linked static sites can often skip them.
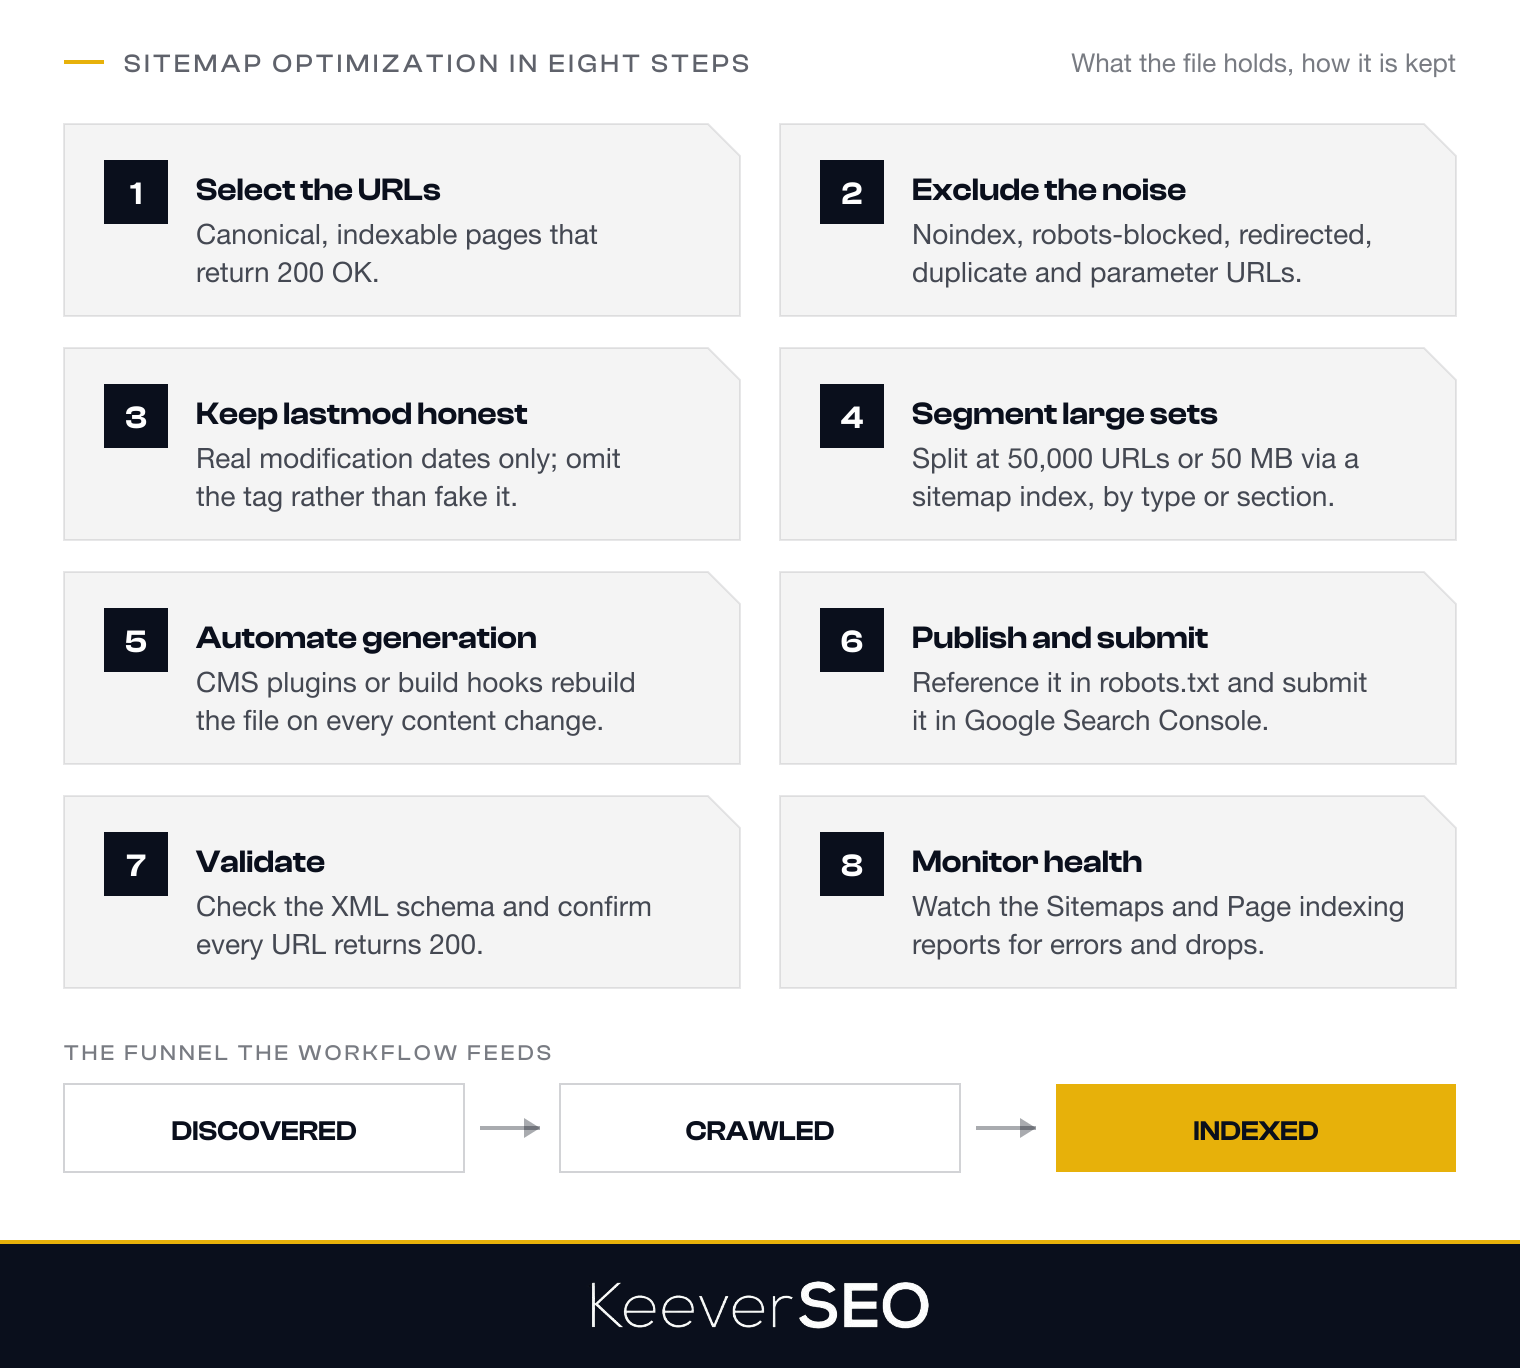
Optimizing a sitemap for better discovery runs through eight steps. First, choose which URLs to include, such as canonical, indexable, 200-status pages, and exclude noindex, robots-blocked, redirected, duplicate, or parameter URLs. Next, keep lastmod metadata accurate so it signals real freshness. Segment large and specialized sitemaps by splitting files at the 50,000-URL or 50 MB limits through a sitemap index. For dynamic and JavaScript sites, implement auto-generated sitemaps with headless rendering or CMS plugins that regenerate on content changes. After that, publish the sitemap by referencing it in robots.txt and submitting it in Google Search Console with absolute URLs, then validate both the XML schema and the URL status codes so the file stays error-free. Finally, monitor sitemap health through Search Console's Sitemaps and Page indexing reports and track the discovered-to-crawled-to-indexed funnel.
A sitemap needs technical SEO attention when warning signs appear, such as indexing drops, crawl errors, or stale and bloated files, and a full sitemap audit is warranted when the symptoms persist or worsen. Hiring an SEO agency like SEO Agency In USA becomes the right move when sitemap issues are complex, site-wide, or tied to broader technical SEO problems such as poor crawl budget management or weak internal linking. An agency checks beyond the sitemap itself, auditing the internal links that support crawl discovery, crawl budget allocation on large sites, and the other discovery signals that affect indexing. Sitemap optimization connects to better discovery because it helps search engines find, crawl, and index a site's most important content, and the connection starts with the definition below.
What Is a Sitemap?
A sitemap is a file that lists the URLs of a website together with metadata about each one, so search engines can read the site's structure without following every link. A sitemap differs from a normal webpage because it is not written for visitors: the file carries no design, navigation, or body copy, only a machine-readable list of addresses and the data attached to them, such as the last modification date.
The sitemap format that search engines read is XML, the eXtensible Markup Language defined by the Sitemaps protocol. Each entry in an XML sitemap wraps a URL in tags that crawlers parse, which turns the file into a metadata-carrying list rather than a plain index of links.
The roadmap concept explains the sitemap's role: the file shows a crawler where the important pages live and which ones changed, much as a road map shows a driver the routes worth taking. A sitemap does not decide what gets indexed, but it tells search engines which URLs the site owner considers worth a visit.
How Does a Sitemap Differ From Website Navigation?
A sitemap differs from website navigation in its audience: a sitemap is a crawler-focused file that lists URLs and metadata for search engines, while website navigation, such as menus and internal links, guides visitors through a site. Navigation moves people; a sitemap signals crawlers.
A sitemap is not the same as internal links. Internal links establish pathways and context for both users and search engines, whereas a sitemap acts as a supplemental tool that highlights URLs that may be hard to reach through navigation, such as orphaned or deeply nested pages. A sitemap cannot replace the structural role of internal links, which shape the crawlability and user experience of a website.
How Does a Sitemap Work?
A sitemap works as a discovery file that search engines read to identify the pages of a website and its structure. The sitemap is stored as an XML file and lists the URLs of a website along with metadata such as the last modification date, change frequency, and priority of each page. The structured format lets search engines like Google access and evaluate the available pages without relying on internal links alone for page discovery.
The XML sitemap protocol gives webmasters a standardized way to communicate page details to search engines. Search engines read the sitemap and prioritize which pages to crawl based on the metadata, so newly published or updated content is discovered faster. The benefit is greatest for websites with complex structures, new sites with few inbound links, and content-heavy sites where important pages might otherwise stay undiscovered.
A sitemap serves as a suggestion rather than a command. The file guides crawlers toward important URLs and indicates content freshness through the lastmod attribute, but it does not guarantee that every listed page will be crawled or indexed. Search engines apply their own criteria to decide which pages enter the index and use the sitemap to speed up discovery and crawl efficiency.
How Do Search Engines Use Sitemaps?
Search engines use sitemaps as a discovery tool to find and prioritize website pages for crawling. When a crawler like Googlebot reads a sitemap, it takes in the listed URLs and their metadata, such as last modification dates, which helps it decide which pages to crawl first and how often to revisit them. A sitemap remains a hint rather than a directive, so search engines are not obliged to crawl or index every URL listed; Google's "Build and Submit a Sitemap" documentation states that submitting a sitemap does not guarantee Google will download it or use it for crawling. Sitemaps raise crawl efficiency by surfacing pages that are otherwise hard to find, such as orphaned pages or newly published content.
What Is the XML Sitemap Protocol Structure?
The XML sitemap protocol structure is a standardized format that organizes website URLs and related metadata in a machine-readable file for search engines. An XML sitemap opens with the <urlset> tag, which wraps every URL entry and declares the namespace, most often xmlns="http://www.sitemaps.org/schemas/sitemap/0.9". Each webpage appears as a <url> element with child tags that describe that URL.
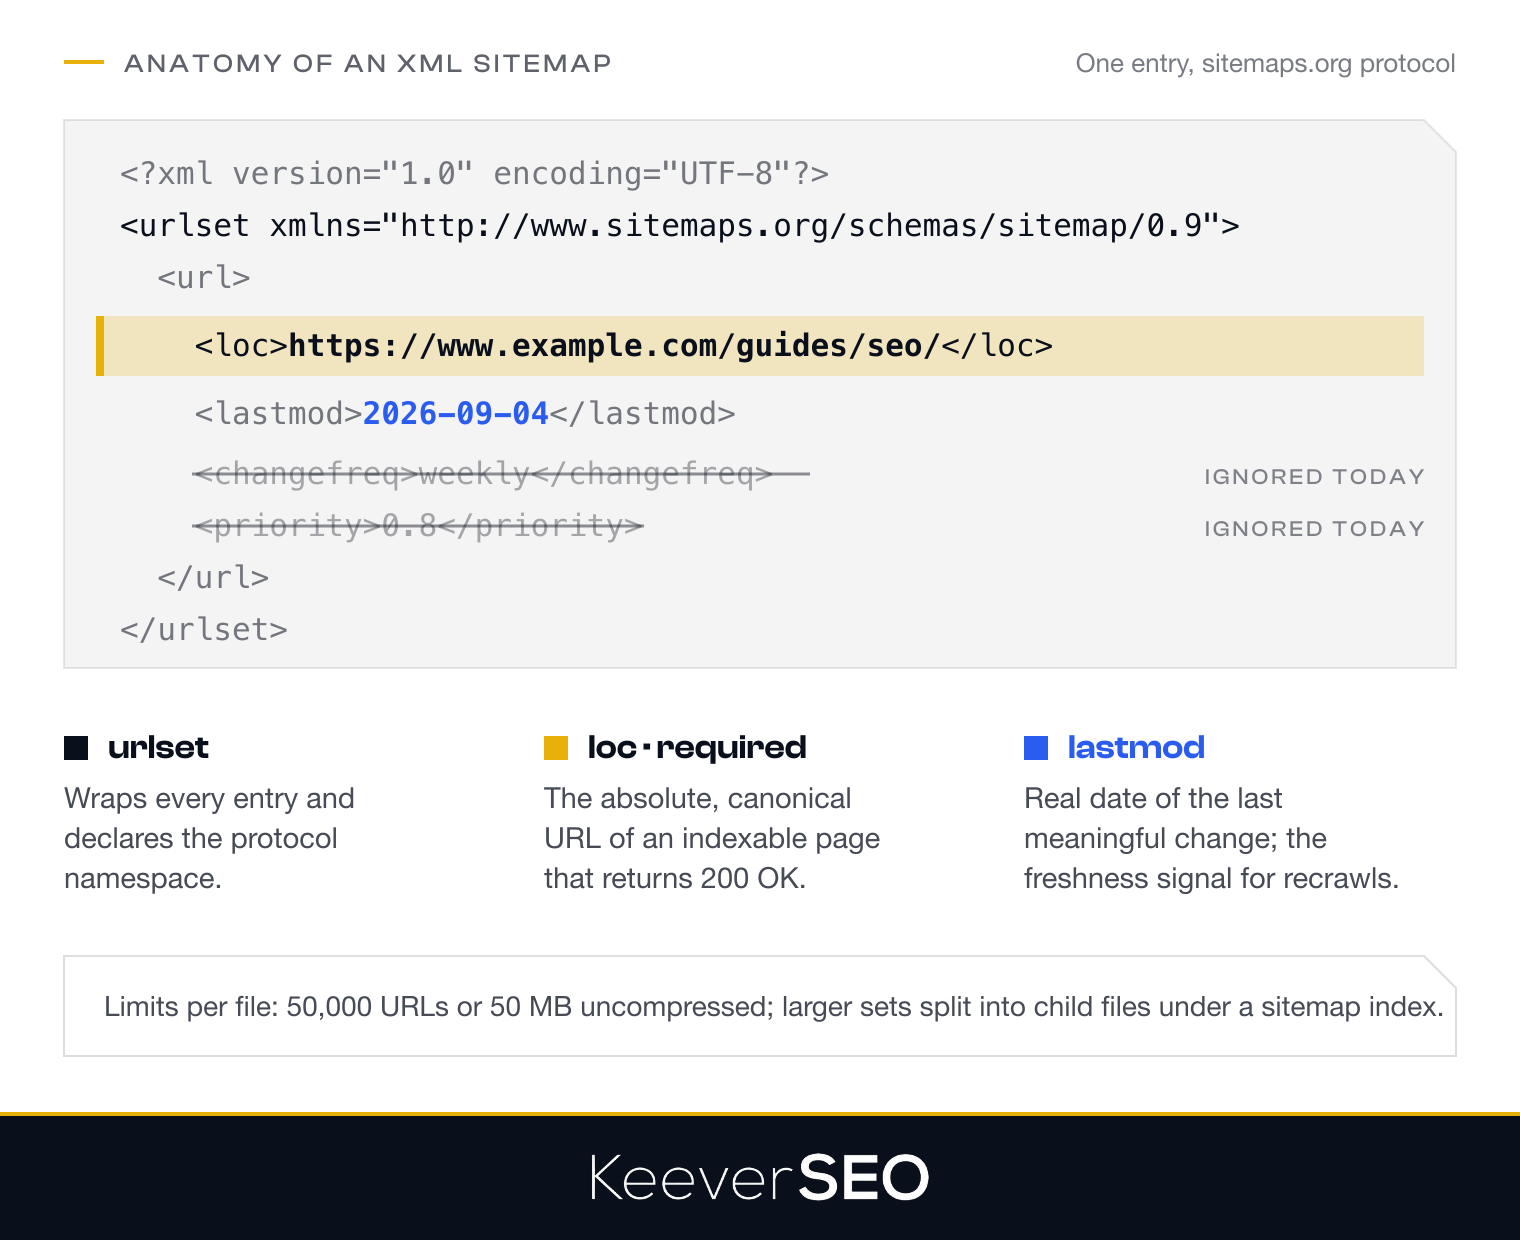
The <loc> tag carries the absolute URL of the page and is required. The <lastmod> tag records the date of the page's last modification in W3C datetime format (YYYY-MM-DD), which serves as a freshness signal to crawlers. The <changefreq> and <priority> tags were included in the original protocol to suggest how often a page changes and its relative importance, but search engines now disregard them and rely on their own algorithms and the <lastmod> timestamp for crawling decisions. The protocol supports additional tags for video, image, and news sitemaps, while the core structure stays constant: the <urlset> holds several <url> entries, each with at least a <loc> tag and, where accurate, a <lastmod> value.
What Are the Types of Sitemaps?
The types of sitemaps are XML, HTML, image, video, and news sitemaps, plus the sitemap index that groups them. Each type serves a different content need, and the six types are listed below:
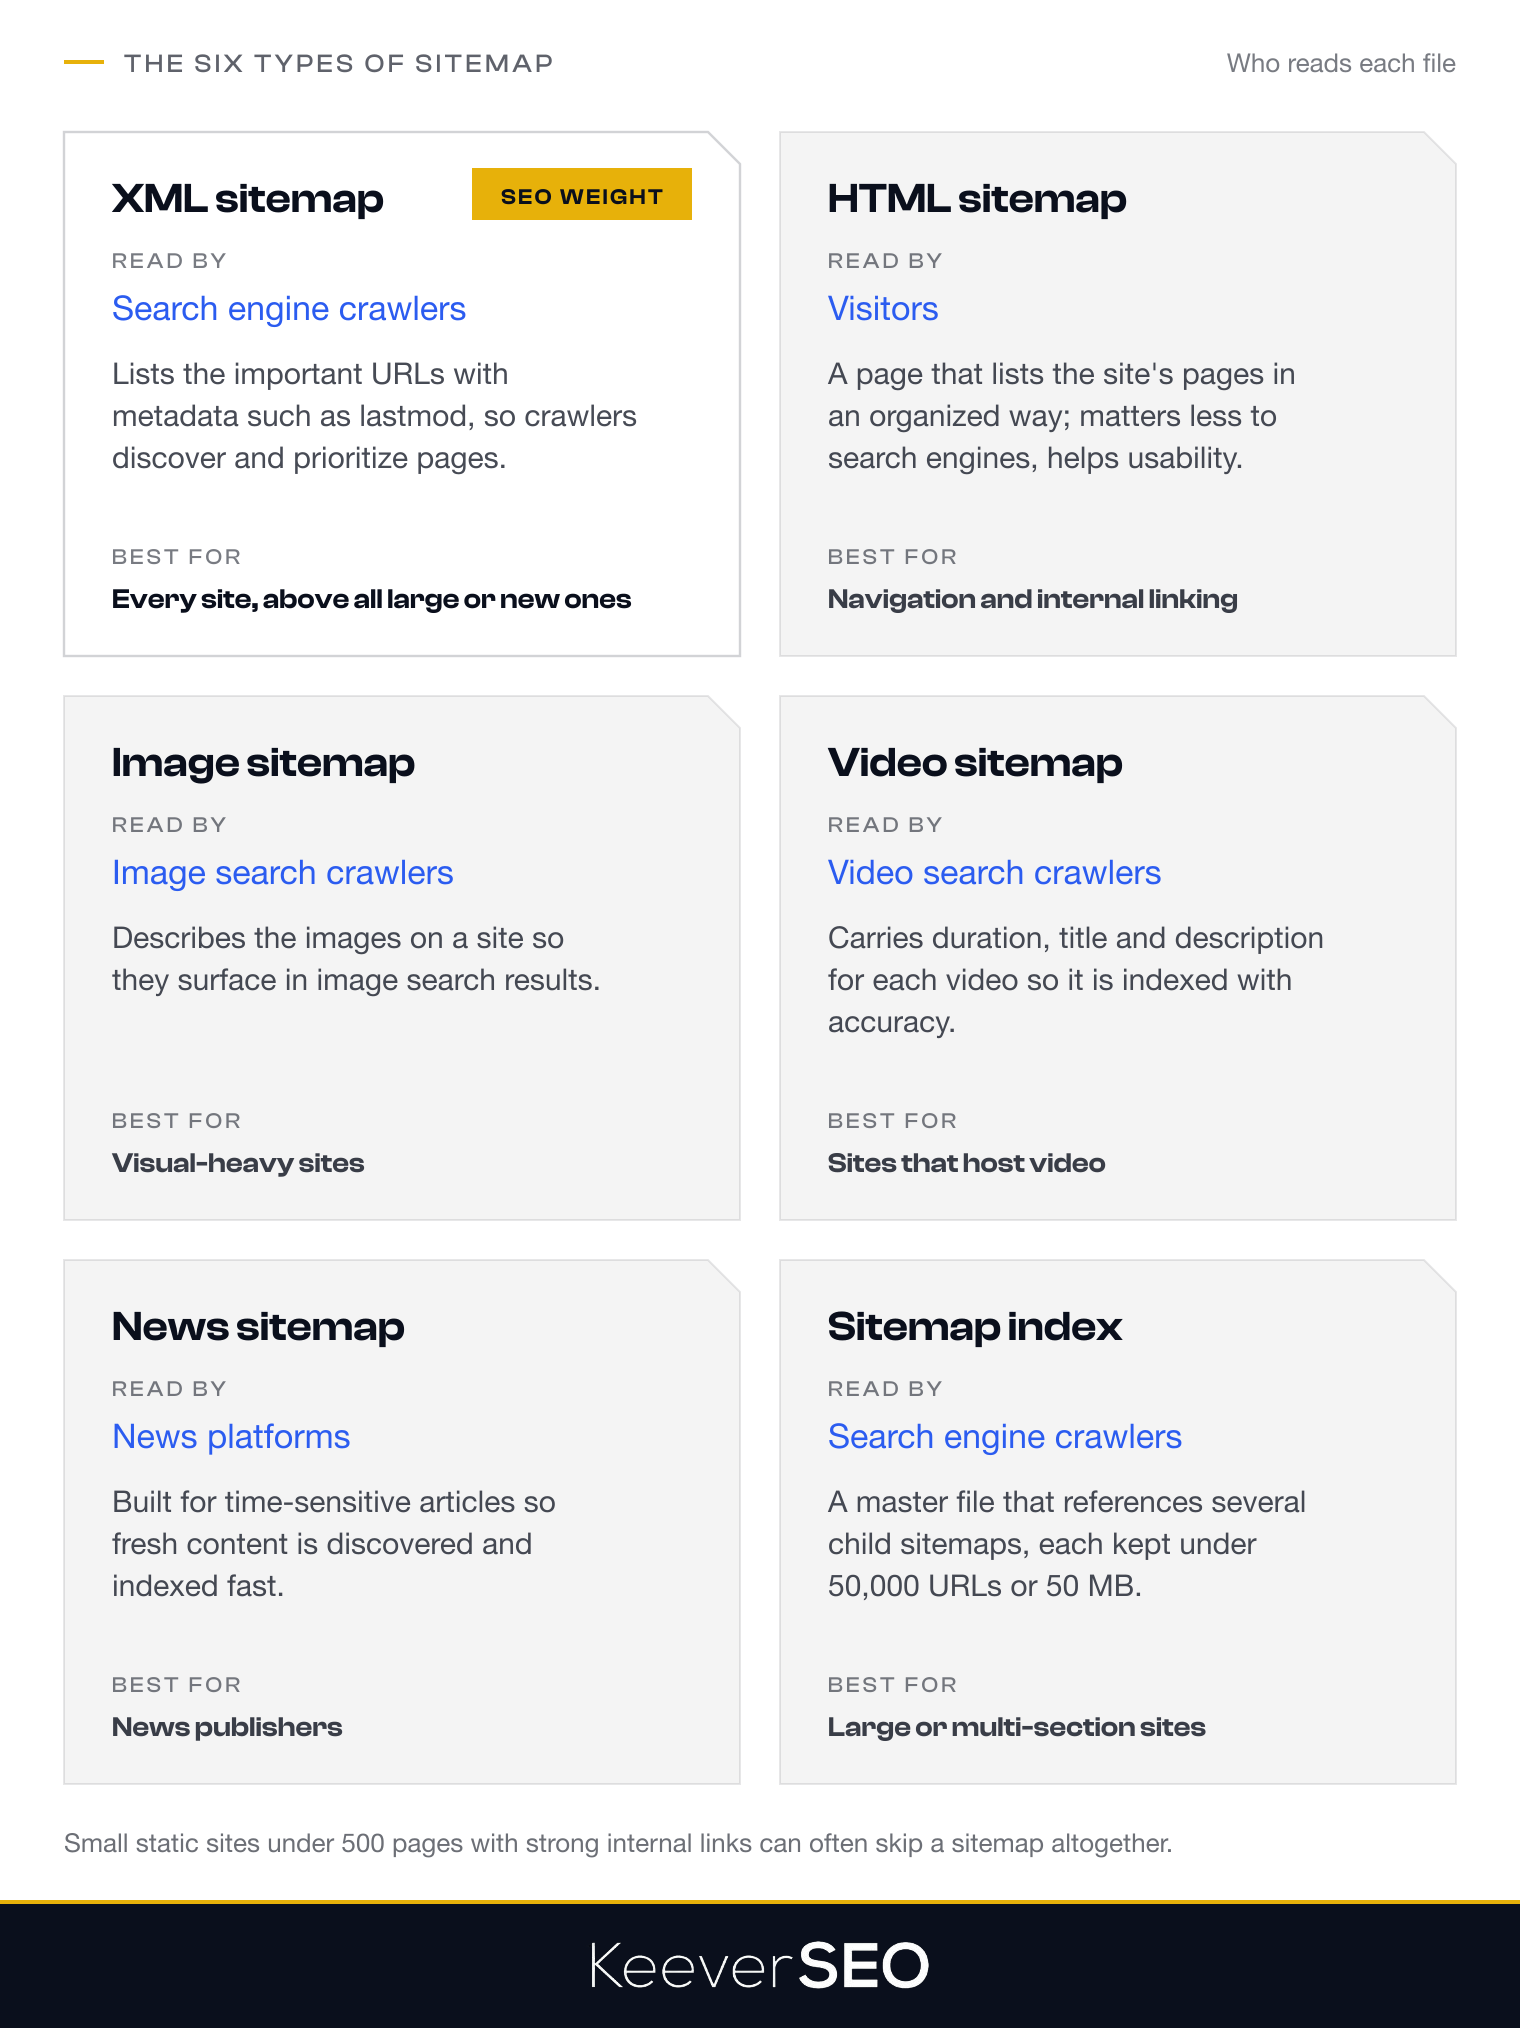
XML Sitemap An XML sitemap is written for search engines. The file lists a website's important URLs with metadata like the last modified date, which supports crawling and indexing. XML sitemaps carry the most SEO weight, above all for large, complex, or new websites.
HTML Sitemap An HTML sitemap is a user-facing page that helps visitors find their way through a site's structure. The page gives an organized list of pages that makes content easier to find, and while it matters less to search engines, it supports internal linking and site usability.
Image Sitemap An image sitemap helps search engines discover the images on a website. The file carries specific information about image content, which raises visibility in image search results and suits sites with heavy visual content.
Video Sitemap A video sitemap supplies detailed metadata about video content, such as duration, title, and description, so search engines index video content with more accuracy. Sites that host video need one for proper discovery and indexing.
News Sitemap A news sitemap is built for time-sensitive news content and speeds the indexing of articles for platforms like Google News. News publishers rely on it to get fresh content discovered and indexed fast.
Sitemap Index A sitemap index is a master file that references several individual sitemaps. The index applies when a website holds many URLs or needs its sitemaps organized into logical groups, such as by content type or section, within the 50,000-URL and 50 MB limits per sitemap file, which makes it the standard structure for large or complex websites.
Why Do XML Sitemaps Still Matter for SEO?
XML sitemaps still matter for SEO because they improve indexing efficiency, surface orphan pages, and communicate freshness. The files give search engines a structured list of important URLs, which helps them prioritize which pages to visit and when. XML sitemaps do not lift rankings on their own, yet they raise crawl efficiency by getting important pages discovered even when internal links are thin. Google's documentation states that search engines use sitemaps to learn which pages the site owner considers important. Botify crawl data reported by Search Engine Land found that Google misses about half of the pages on large enterprise sites, which is the discovery gap a sitemap helps close, so XML sitemaps carry the most value for large sites, new sites, thinly linked sites, JavaScript-heavy sites, and media-rich sites that depend on strong discovery signals.
Who Needs a Sitemap?
The websites that need a sitemap most are large sites, new or thinly linked sites, JavaScript-heavy sites, and media-rich sites. Large websites with hundreds or thousands of pages need sitemaps so search engines discover every important page. New websites, or sites with few external backlinks, rely on sitemaps because they lack the inbound link signals that lead search engines to their pages. JavaScript-heavy sites, single-page applications (SPAs), and dynamically generated websites gain from sitemaps because their content can be hard for crawlers to render and discover without an explicit URL list. Media-rich sites with extensive image, video, or news content should use specialized sitemaps to surface that content with the right metadata for indexing.
Small static sites with fewer than 500 pages and strong internal linking may not need a sitemap, because search engines can crawl and index them through the link structure alone. Knowing which site profiles need a sitemap sets up the work of optimizing that sitemap for crawl discovery and indexing efficiency.
How Do You Optimize a Sitemap for Better Discovery?
You optimize a sitemap for better discovery through an eight-step workflow that controls what the file contains, how it is structured, and how it is maintained. Start by selecting URLs that are canonical, indexable, and important for search visibility, and exclude URLs that are redirected, blocked, or duplicated so crawlers waste no effort. Keep the <lastmod> tag accurate so it signals real content updates. Segment large sitemaps into manageable files and automate generation on dynamic or JavaScript-heavy sites. Publish the sitemap in robots.txt and submit it to Google Search Console to raise its discoverability, then validate and monitor it at regular intervals to keep it healthy and improve indexing. The first step in the workflow is deciding which URLs belong in the file.
Step 1: Which URLs Should a Sitemap Include?
A sitemap should include the URLs that search engines need to index: canonical, indexable pages that return a 200 OK status code. Primary content, core product pages, and updated blog posts are typical inclusions, because they represent the content the site wants discovered and ranked. The three inclusion criteria are listed below:
- Canonical URLs: Each URL must be the preferred version, not a duplicate or alternate path.
- Indexable Pages: Only pages meant to appear in search results belong in the file.
- 200 Status Code: Each URL must return a 200 OK status, which confirms it is accessible and working.
Meeting the three criteria keeps the sitemap a high-quality resource for search engines and raises the odds of efficient, complete indexing. The next step identifies the URLs that should be excluded to protect that quality.
Step 2: Which Redirected, Blocked, Noindex, and Duplicate URLs Should a Sitemap Exclude?
A sitemap should exclude noindex pages, robots-blocked URLs, redirected URLs, canonicalized duplicates, and parameter or session URLs. A well-maintained sitemap keeps search engines focused on the most valuable content without spending resources on non-indexable pages. The five exclusion categories are listed below:
- Noindex Pages: Any page marked with a noindex directive stays out of the sitemap, because listing it sends mixed signals: the sitemap suggests indexing while the noindex tag forbids it.
- Robots-Blocked URLs: URLs blocked by the robots.txt file stay out of the sitemap, since search engines cannot crawl them and their inclusion only creates confusion.
- Redirected URLs (3xx Status Codes): URLs that redirect, such as those with 301 or 302 status codes, stay out of the sitemap, and only the final destination URL is listed, which protects crawl budget and speeds page discovery.
- Canonicalized Duplicate URLs: When a page names a canonical URL elsewhere, the non-canonical version leaves the sitemap so search engines focus on the preferred version of the content.
- Parameter and Session URLs: URLs with session IDs, tracking parameters, or filter strings often create duplicate content, so only the clean canonical versions belong in the file.
Excluding the five categories keeps the sitemap focused on the pages that matter for indexing, which raises the site's visibility and crawl efficiency.
Step 3: How Should You Use Accurate lastmod Metadata?
You should use accurate lastmod metadata by setting the <lastmod> tag to the true date of a page's last meaningful modification, such as an update to the main content, structured data, or links. The tag serves as a freshness signal that helps search engines decide when a page warrants recrawling. Faked dates, or a lastmod bumped for minor changes like footer edits, erode trust and waste crawls.
To keep the value accurate, tie lastmod to the content changes recorded in the content management system's edit logs. When real modification times cannot be tracked, omitting the lastmod tag beats supplying misleading dates. Reserving a fresh lastmod for pages with meaningful updates lets crawlers identify which URLs need immediate attention, which sharpens the speed and precision of content discovery and indexing.
Step 4: How Should You Segment Large and Specialized Sitemaps?
You should segment large and specialized sitemaps by splitting them into a sitemap index with child files organized by type, media, or site section. The Sitemaps protocol published at sitemaps.org caps each file at 50,000 URLs or 50 MB uncompressed, so larger sites must split their sitemaps to stay within the limits. The three segmentation approaches are listed below:
Sitemap Index File A sitemap index file acts as a master list that references several child sitemaps. The structure keeps URLs organized and within the size constraints, and it gives search engines a single entry point for the whole set.
Segmentation by Type and Media Dividing sitemaps by content type, such as pages, images, or videos, clarifies the file set and improves discovery. The split helps search engines prioritize crawling and indexing by content relevance and format.
Segmentation by Site Section Organizing sitemaps by site section, such as /blog/, /products/, or /support/, refines crawl efficiency further. The split lets search engines focus on specific areas of a website, and it shows in Search Console which section is losing coverage.
The three segmentation strategies keep the sitemap structure organized and support better discovery and indexing performance.
Step 5: How Should Dynamic and JavaScript Websites Generate Sitemaps?
Dynamic and JavaScript websites should generate sitemaps through automation that compiles URLs as content is created or updated. Sites of that kind generate content on the fly or render it client-side, which static sitemap methods cannot capture. Auto-generation through server-side scripts, content management systems (CMS), or dedicated plugins keeps the file in step with the site.
For single-page applications (SPAs) and headless frameworks built with React, Vue, or Angular, the sitemap generator must read the fully rendered HTML output. Server-side rendering (SSR), static site generation (SSG), or a headless rendering service that executes JavaScript before extracting URLs each solve the problem. CMS platforms like WordPress and Shopify offer native sitemap generation or plugin support, such as Yoast SEO or Rank Math, which regenerate the sitemap whenever pages are published, updated, or deleted.
For custom-built dynamic sites, auto-regeneration triggers tied to database events, such as post publication, product additions, or content modification, keep the sitemap current without manual work. The event-driven approach gives search engines an up-to-date list of crawlable URLs. Once dynamic sitemap generation is in place, the next step publishes the file and submits it to search engines.
Step 6: How Do You Publish a Sitemap in robots.txt and Submit It in Google Search Console?
You publish a sitemap by referencing it in robots.txt and then submitting it in Google Search Console. First, add a Sitemap: directive to the robots.txt file followed by the absolute URL of the sitemap, such as Sitemap: https://www.example.com/sitemap.xml. Crawlers check robots.txt among the first resources on a site, which makes it the natural place to declare the sitemap.
Next, submit the sitemap through Google Search Console: open the Sitemaps section, enter the sitemap URL, and submit it for processing. Search Console then verifies the file and reports any errors or issues. For broader coverage, submit the sitemap to Bing Webmaster Tools as well. Completing both steps gives search engines several discovery pathways and maximizes the sitemap's discovery value.
Step 7: How Do You Validate Sitemap Files and URL Statuses?
You validate sitemap files and URL statuses by checking the XML structure first and then the status code of every listed URL. The two checks confirm that search engines can process and trust the file.
Schema and XML Validation The first check confirms that the sitemap follows the XML sitemap protocol: a well-formed XML structure with correct tags such as <urlset>, <url>, and <loc>. Google Search Console flags parsing errors, which keeps the sitemap readable and free of syntax issues.
URL Status-Code Validation The second check runs a full status-code sweep of every URL in the sitemap to confirm each returns a 200 (OK) status. The sweep exposes URLs that redirect (3xx), return errors (4xx or 5xx), or are blocked by robots.txt. Tools like Screaming Frog handle manual checks, and automated scripts handle larger datasets. An error-free sitemap that passes both schema validation and status-code verification signals to search engines that the site is well maintained, which lifts crawl efficiency and discovery performance.
Step 8: How Do You Monitor Sitemap Health and Discovery Performance?
You monitor sitemap health and discovery performance through Google Search Console's Sitemaps and Page indexing reports. The reports show how many URLs were submitted, how many were discovered, and which errors appeared during processing, which confirms that search engines read the sitemap and accept the URLs it lists.
Tracking discovery performance means following the discovered-to-crawled-to-indexed funnel: how many sitemap URLs Googlebot discovers, how many it crawls, and how many it indexes. The Page indexing report sorts URLs into indexed pages, excluded pages, pages with errors, and pages with warnings, which exposes indexing anomalies. Regular checks for crawl errors, indexing drops, and stale or bloated URLs keep the sitemap healthy, and the same signals show when a sitemap needs technical attention, such as cleaning up excluded URLs, fixing crawl errors, or addressing broader site architecture issues.
When Does a Sitemap Need Technical SEO Attention?
A sitemap needs technical SEO attention when warning signs point to crawling or indexing problems. The most common indicators are sudden drops in indexed pages, persistent crawl errors, and stale or bloated sitemap files. The issues lead to inefficient crawling and indexing, which weakens website visibility and performance. When the symptoms appear, a full sitemap audit is warranted to find and fix the underlying problems, as part of a broader technical SEO check on site health and discoverability.
When Should a Website Request a Sitemap Audit?
A website should request a sitemap audit when persistent technical issues surface. One trigger is Google Search Console reporting ongoing crawl errors or excluded URLs tied to the sitemap. A site migration, major redesign, or substantial content update calls for an audit as well, because each can break the sitemap's alignment with the website's structure. A sitemap bloated with outdated URLs, which drags down crawl efficiency, is a further trigger.
A sitemap audit makes sense when unexplained gaps open between submitted and indexed URLs, which point to discovery problems. Websites with stagnant organic traffic despite regular content updates should audit the sitemap to confirm it reflects the site's current structure. An audit is warranted as well when the internal team lacks the expertise to resolve recurring sitemap-related indexing issues.
When Should You Hire an SEO Agency for Sitemap Optimization?
You should hire an SEO agency for sitemap optimization when the technical SEO issues extend beyond simple sitemap adjustments. The issues include persistent indexing drops, inefficient crawling, or complex site structures that keep search engines from discovering important pages. Large, dynamic, or media-heavy sites gain the most from professional intervention, because those environments need coordinated work across crawl management, internal linking, and automated sitemap generation. Our search engine optimization services team is the right choice when a sitemap needs more than basic file cleanup and submission: the team examines internal linking, optimizes crawl budget, handles canonicalization, and manages noindex directives, which gives full indexing support.
What Should an SEO Agency Check Beyond a Sitemap?
An SEO agency should check internal linking, crawl budget, and discovery signals beyond the sitemap itself. Internal linking decides whether search engines can move through the site and prioritize important pages, and a well-structured internal link architecture distributes PageRank and aids the discovery of core content.
Crawl budget management comes next. The crawl budget sets how many pages a search engine will crawl, and efficient use of that resource matters on large websites. The agency assesses whether the site wastes crawl capacity on low-value or error-prone URLs and makes sure the most important pages come first.
Discovery signals such as robots.txt directives, canonicalization, and URL parameter handling round out the review, because they shape how search engines index and rank a site. Auditing the signals lets the agency confirm that search engines can find, access, and index a site's valuable content, and the three areas are broken down below.
How Do Internal Links Support Crawl Discovery?
Internal links support crawl discovery by creating the pathways that search engine crawlers follow to find a website's pages. When a crawler lands on a page, it scans the internal links for additional URLs to visit, which lets it map the site structure and reach deeper pages that would otherwise stay hidden. Strong internal linking directs crawler attention to important pages and signals content relationships and hierarchy to search engines. The interconnected structure helps crawlers move through the site and read which pages matter most by how often they are linked internally.
Internal links are the backbone of discovery, which raises the question of whether a sitemap can replace them.
Can a Sitemap Replace Internal Linking?
No, a sitemap cannot replace internal linking. Sitemaps help search engines discover URLs, but internal links supply the navigation paths and context that a sitemap lacks. Internal links establish site structure and distribute PageRank, which a sitemap alone cannot do, and they guide both users and crawlers through content hierarchies while signaling page importance through link frequency and prominence. A sitemap serves as a supplementary discovery tool, above all for orphaned pages, but it cannot replicate the architectural benefits of internal linking.
How Does Crawl Budget Affect Large Websites?
Crawl budget affects large websites by capping how many pages a search engine will crawl within a given period. On very large sites, bloat wastes the budget on low-value URLs, such as redirected or duplicate pages, and leaves important content undiscovered. Prioritizing core pages through a well-structured sitemap directs the limited budget toward the pages that matter, which raises discovery and indexing efficiency, a constraint Google's "Large Site Owner's Guide to Managing Your Crawl Budget" reserves for sites with more than a million unique pages or more than 10,000 pages updated daily.
How Does Sitemap Optimization Support Better Discovery?
Sitemap optimization supports better discovery by giving search engines a structured guide to a website's most important pages. An optimized sitemap lists only indexable, canonical URLs with 200 status codes, which keeps search engines like Googlebot focused on content that should be indexed. Accurate lastmod metadata signals real freshness and prompts faster recrawls of updated pages. For sites with deep architectures, frequent updates, or rich media, an optimized sitemap speeds the discovery of new and orphaned pages that link-based crawling alone might miss.
Precise URL selection, reliable metadata, proper segmentation, and ongoing monitoring through Google Search Console combine to deliver the better-discovery outcome that drives efficient indexing. A website's most valuable content then reaches search engine indexes faster and more completely, which is the whole point of a sitemap.