The search engine indexing mechanism is the process by which search engines collect, interpret, and store web content in a structured database so it can be retrieved fast during user queries. An index acts as a catalog of web pages, much like a library's card catalog, and a page that is not indexed cannot rank in search results regardless of its quality. Indexing differs from crawling, the discovery phase where bots move across the web, and from ranking, where indexed content is sorted by relevance. The indexed set forms the pool of eligible content from which search results pages are populated.
The indexing mechanism processes a page through several stages: fetching the HTML, rendering JavaScript where needed, parsing the content structure, tokenizing text into searchable terms, and storing the tokens in the index database. URLs enter the pipeline through discovery routes such as XML sitemaps, internal and external links, and direct submission methods like IndexNow. An inverted index architecture supports the index by mapping each term to the list of documents that contain it, which allows rapid lookup when a query runs. Parsing HTML means recognizing document sections like titles and headings, assigning priority weights to HTML elements, processing meta tags, and applying natural language processing to grasp semantic context and user intent.
A page's crawlability and indexability rest on distinct criteria: crawlability depends on server accessibility and the absence of blocking directives in robots.txt, while indexability requires sufficient content quality, uniqueness, sound canonicalization signals, and no noindex directives. Technical controls such as robots meta tags and canonical tags govern a page's entry into the index, while site architecture, XML sitemap hygiene, and crawl budget allocation decide which pages receive enough crawler attention. JavaScript-heavy sites and mobile-first indexing add complexity, because JavaScript content may wait in a render queue and the mobile version of a page becomes the indexed version. Crawled pages can stay unindexed because of quality issues, duplicate content detection, or directive conflicts, and index status is checked with tools like Google Search Console's URL Inspection tool. Indexing diagnosis supports technical SEO by separating crawlability from indexability issues into distinct remediation tracks, and an indexing audit examines crawl access paths, index eligibility signals, directive conflicts, sitemap accuracy, and content quality thresholds. Businesses should engage a specialist agency like SEO Agency In USA when indexing problems occur at scale, with crawlability restored first and indexability addressed next. Improvement is measured by tracking shifts in Search Console coverage statuses, and healthy index coverage is preserved through ongoing maintenance routines that return, in the end, to the question of what search engine indexing is.
What is search engine indexing?
Search engine indexing is the process by which search engines discover, analyze, store, and organize web content so it can be retrieved for user queries. The procedure runs through several stages, starting with the discovery of URLs by crawlers like Googlebot, which fetch and render web pages. The fetched content is parsed and broken into searchable units known as tokens, which are stored in a massive database called the index. The index acts as a library catalog that lets search engines retrieve relevant content in response to search queries within milliseconds. A page that is not indexed cannot appear in search results or rank for any search, so its visibility is close to zero.
Indexing stands apart from crawling and ranking. Crawling is the initial stage where pages are discovered, while indexing covers the storage and interpretation of content. Ranking is the final stage where indexed pages are ordered by relevance to a user's search query. The differences between the three stages decide how web content should be optimized, and the comparison below sets them side by side.
How does indexing differ from crawling and ranking?
Indexing differs from crawling and ranking in what each stage does and what it produces. The three stages are compared in the table below:
| Stage | What happens | Output/result |
|---|---|---|
| Crawling (discovery) | Automated bots such as Googlebot move across the web, following links and sitemaps to discover new and updated pages and downloading their content. | A collection of raw webpage data and identified URLs ready for processing. |
| Indexing (storage and interpretation) | Downloaded content is parsed, rendered, tokenized, and analyzed; meaningful content is extracted and stored in the search engine's database with term-to-document mappings. | A structured, searchable database (the index) that holds processed content organized for retrieval. |
| Ranking/serving (ordering) | When users submit queries, the search engine matches terms against the index, retrieves relevant documents, and orders them with ranking algorithms based on relevance and quality factors. | An ordered search results page that displays the most relevant indexed content for the user's query. |
Crawling discovers pages, indexing analyzes and stores them, and ranking decides their order of appearance in search results.
How does indexing affect Google Search results pages?
Indexing decides which pages can appear on Google Search results pages, because only indexed content is eligible for display in response to user queries. The indexed set acts as the full pool from which the search engine draws and ranks pages by relevance and other ranking factors. A page with high-quality content will not appear in search results unless it belongs to the index. Once indexed, pages are evaluated for query relevance and other signals, which decide their position in search results.
How does the search engine indexing mechanism process a web page?
The search engine indexing mechanism processes a web page through a series of structured steps that convert raw HTML into structured, searchable data. First, the mechanism fetches the HTML document from the server and retrieves the entire page content. Next comes the rendering phase, where the search engine executes JavaScript and applies CSS to create a fully rendered version of the page that resembles what a user would see in a browser. Rendering matters for modern web pages that depend on JavaScript to display content.
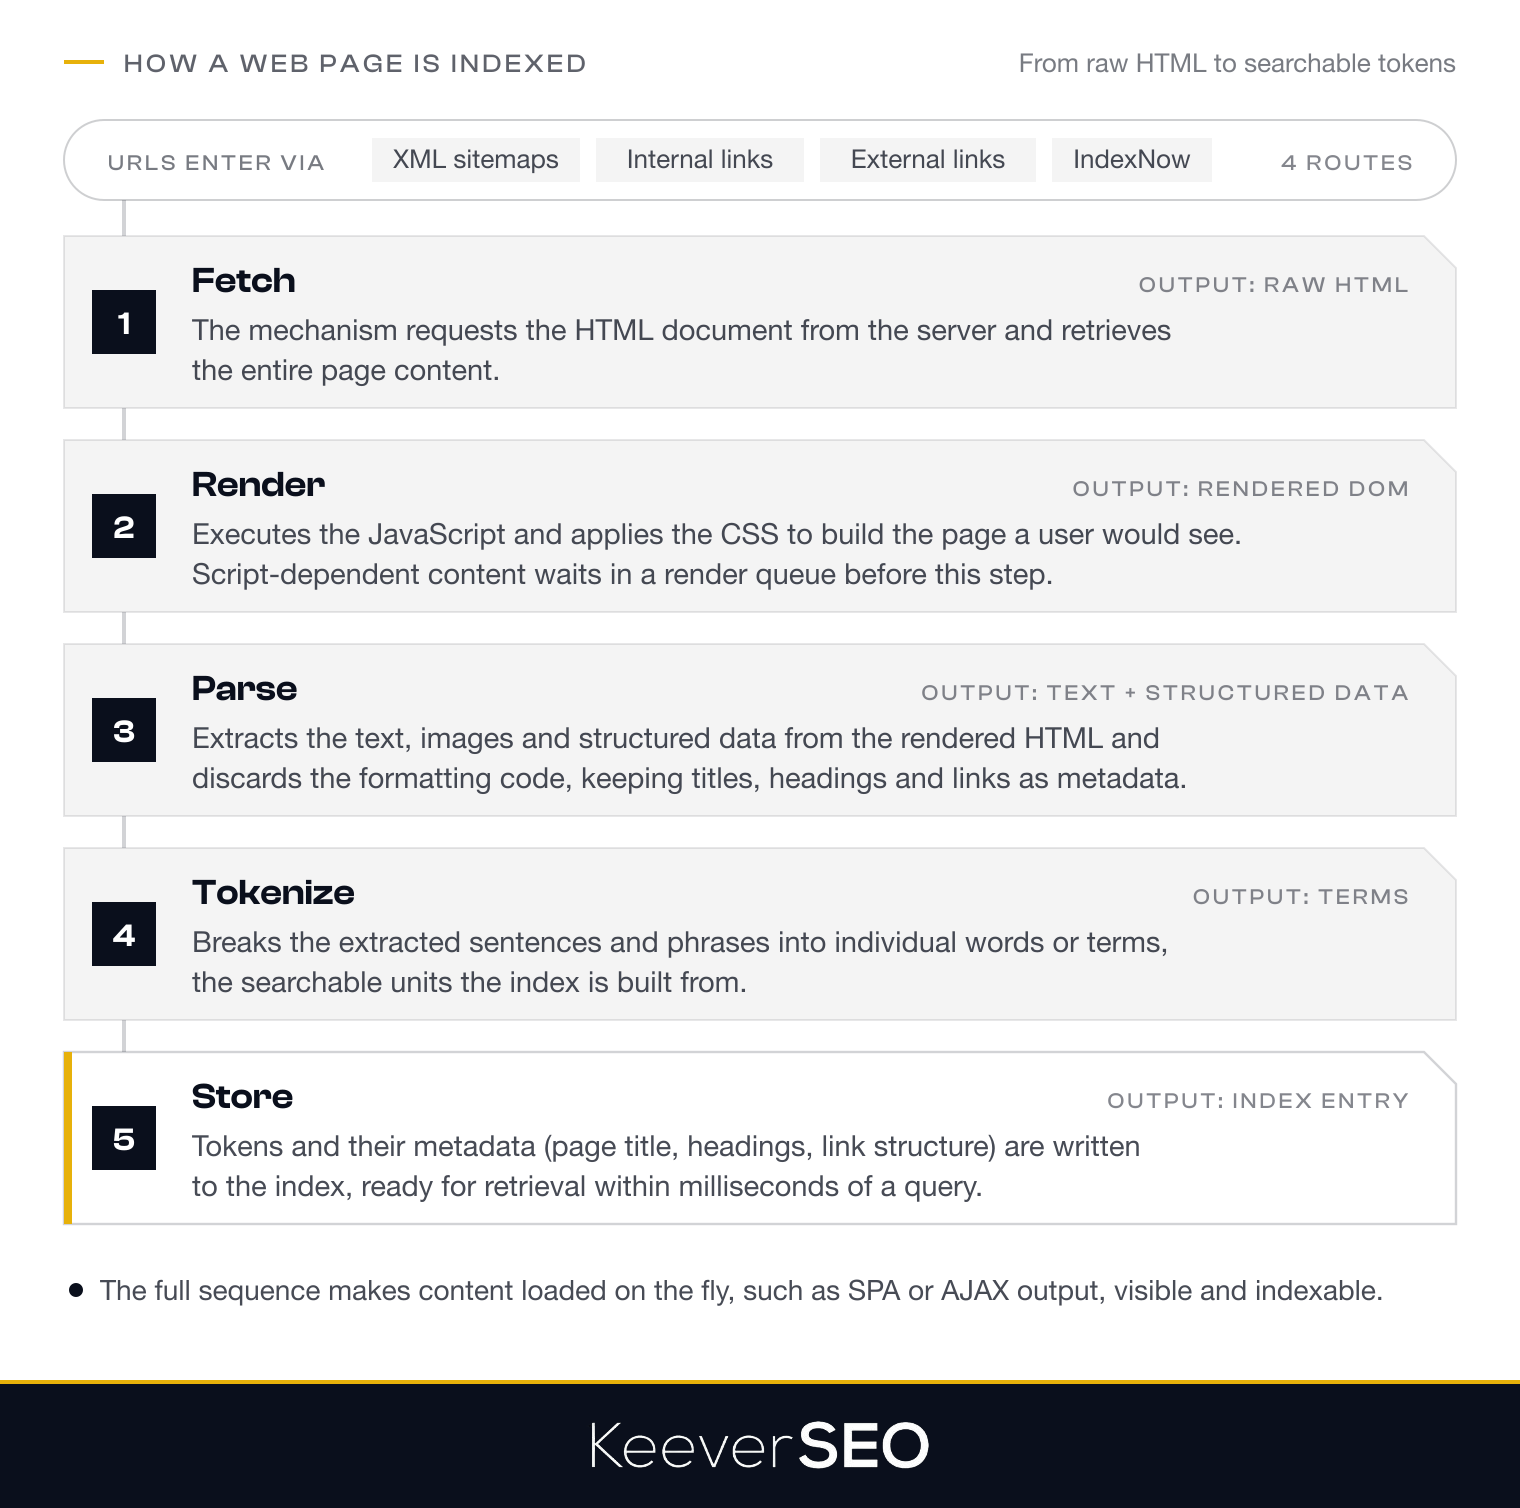
After rendering, the mechanism parses the HTML, extracting textual content, images, and structured data elements while discarding formatting code. The extracted content is then tokenized, which breaks sentences and phrases into individual words or terms. The tokens, along with metadata such as page titles, headings, and link structures, are stored in the search engine's index, which allows rapid retrieval in response to user queries. The full sequence makes content loaded on the fly, such as output from single-page applications or AJAX calls, visible and indexable.
Rendering and content extraction sit at the heart of the indexing pipeline, because they decide which content is prioritized in the index. The pipeline is built for both speed and accuracy, processing billions of web pages while keeping an index that reflects content changes and new publications. The pipeline's effectiveness depends on the quality of the URLs discovered and queued for processing, and the discovery routes are broken down below.
How are URLs discovered before indexing?
URLs are discovered before indexing through four routes, which are listed below:
- XML Sitemaps: XML sitemaps are structured files submitted by site owners that list URLs for search engines to crawl and give a roadmap to the site's most important pages.
- Internal Links: Internal links within a website guide crawlers from one page to the next and surface new or updated content as they move through the site's architecture.
- External Links: Links from other websites, known as backlinks, lead crawlers to new URLs and pass authority signals that can influence indexing priorities.
- Direct Submission through IndexNow: The IndexNow protocol lets site owners notify participating search engines of new, updated, or deleted URLs for immediate discovery without waiting for scheduled crawls.
What is a search engine index and how does an inverted index work?
A search engine index is a database that stores processed information from web pages so it can be retrieved fast during search queries. The index functions as a catalog where every word or token from crawled pages is mapped to the documents that contain it. The mapping is managed through an inverted index, which organizes data around individual terms as keys, each pointing to a list of documents where the term appears. The inverted index works alongside a forward index, which first maps documents to their terms before inversion.
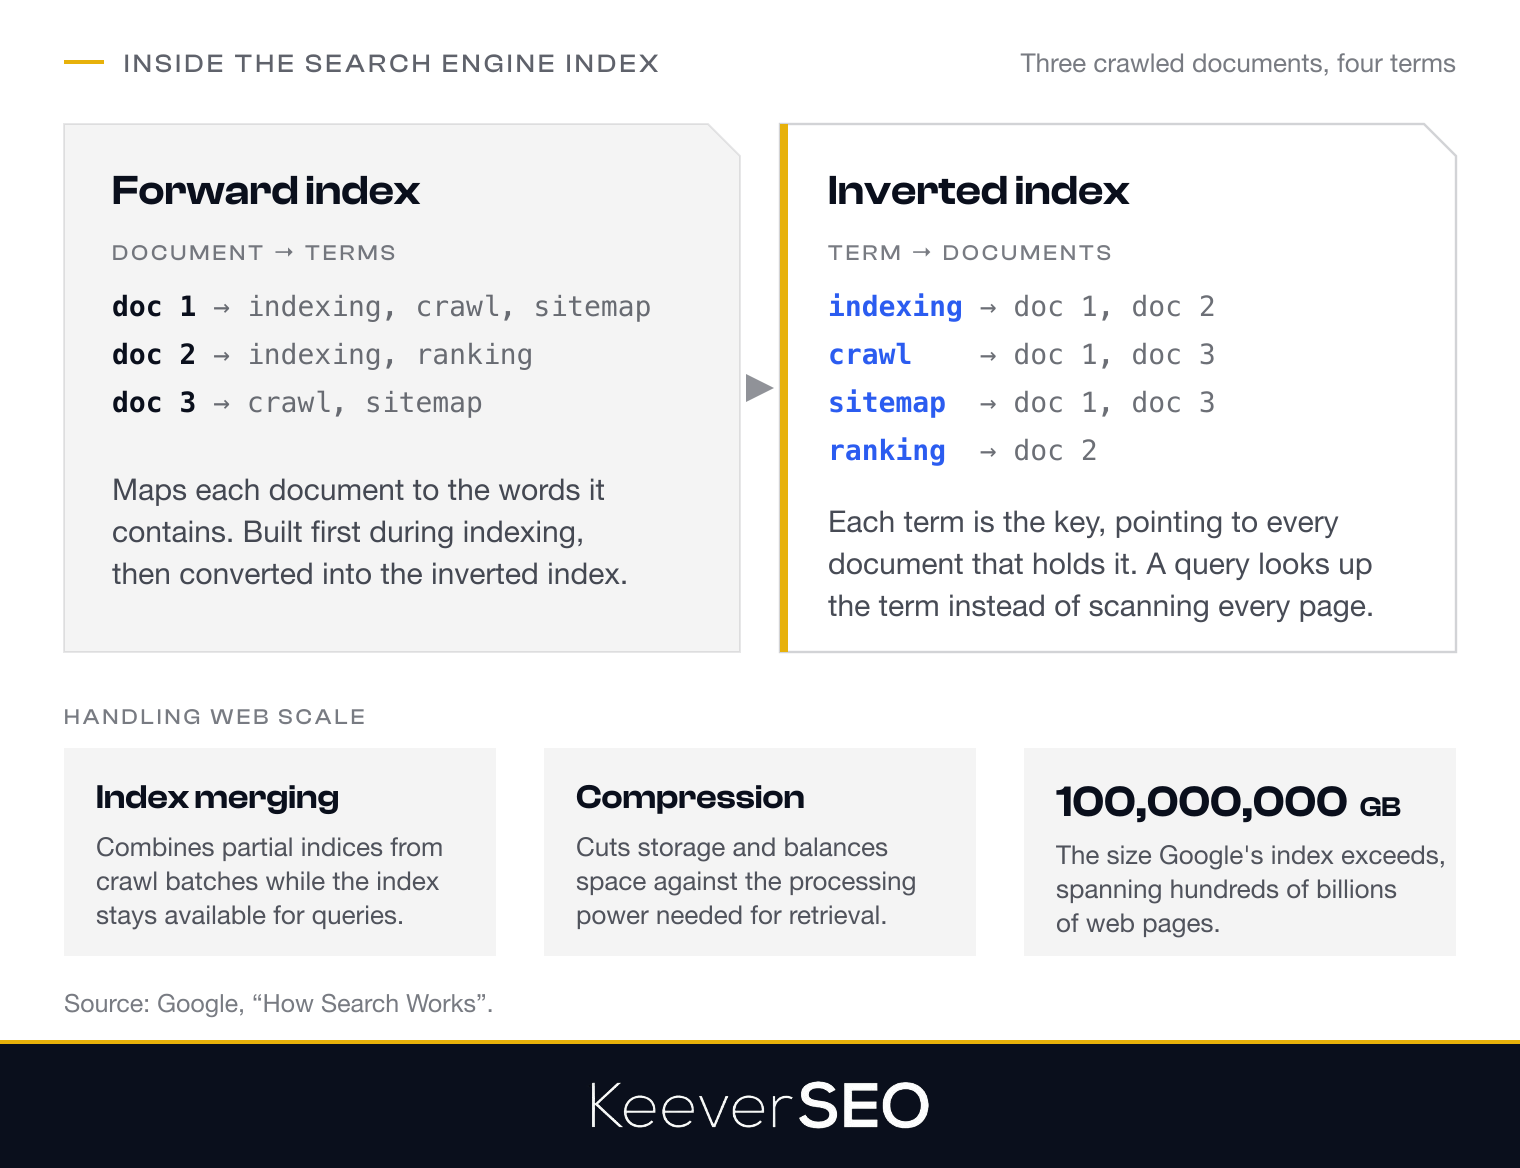
Inverted Index and Forward Index
- Inverted Index: The inverted index reverses the natural document-to-terms relationship, which allows rapid retrieval of documents by search term. The structure sits at the center of search engine efficiency, because it gives quick access to relevant documents without scanning entire databases.
- Forward Index: The forward index maps each document to the words it contains. During indexing, data from the forward index is converted into the inverted index, which shifts the focus to term-to-document mapping.
Index Merging and Compression
Search engines use index merging and compression to handle the vast scale of web data. Merging combines partial indices from different crawl batches while keeping the index available for queries during updates. Compression reduces storage requirements and balances space against the processing power needed for retrieval. Google's index spans hundreds of billions of web pages and exceeds 100,000,000 gigabytes in size, according to Google's "How Search Works" guide, a scale that demands distributed databases and advanced management strategies.
How do search engines parse HTML and understand page meaning?
Search engines parse HTML by transforming web pages into structured, searchable content. Parsing begins with tokenization, where the HTML document is broken into individual words and phrases and formatting code is stripped away. The parser then identifies structural elements such as headings, paragraphs, and lists to read the content's organization. HTML priority weighting follows, which gives more importance to content in title tags and H1 headings because those elements carry the strongest signal about the page's topic and relevance.
Meta tags, such as descriptions and robots directives, support content understanding by supplying signals about the page's purpose and indexing instructions. The shift toward full-text indexing has reduced their primary role. Modern search engines add semantic Natural Language Processing (NLP) to grasp deeper meaning and context. Models like Google's BERT let search engines read relationships between words, interpret user intent, and recognize synonyms, which moves the analysis beyond keyword matching toward the actual subject matter and relevance of a page.
The parsing mechanism produces accurate categorization of content, which lets search engines match pages to relevant queries. The combination of structural HTML analysis and semantic NLP forms the foundation for storing content in the index and retrieving it during ranking.
What makes a web page crawlable and indexable?
A web page is crawlable when search engines can access and move through it, and indexable when it meets the standards to be stored in the index. Crawlability means search engine bots like Googlebot can reach the page through discoverable pathways such as internal links, sitemaps, or external backlinks. Functional server responses and the absence of server-level blocks, such as restrictive robots.txt rules, decide crawlability.
Indexability decides whether a page can be stored in the search engine's database and surface in search results. An indexable page must meet content quality and uniqueness standards, because search engines assess whether the content offers sufficient value, originality, and relevance. Thin, duplicate, or low-quality content may be crawled but rejected from the index.
Canonicalization matters when similar URLs exist, because it helps search engines consolidate duplicates and decide which version should be indexed. Crawlability and indexability form sequential gates: a page must first be reachable by bots, then pass content and technical quality checks to earn a place in the index. The criteria lead into the technical controls, such as robots meta tags and noindex instructions, that govern index eligibility.
How do technical indexing controls affect index eligibility?
Technical indexing controls affect index eligibility by telling search engines which URLs may be crawled, which may be indexed, and which version of a page should represent a set of duplicates. The main controls are compared in the table below:
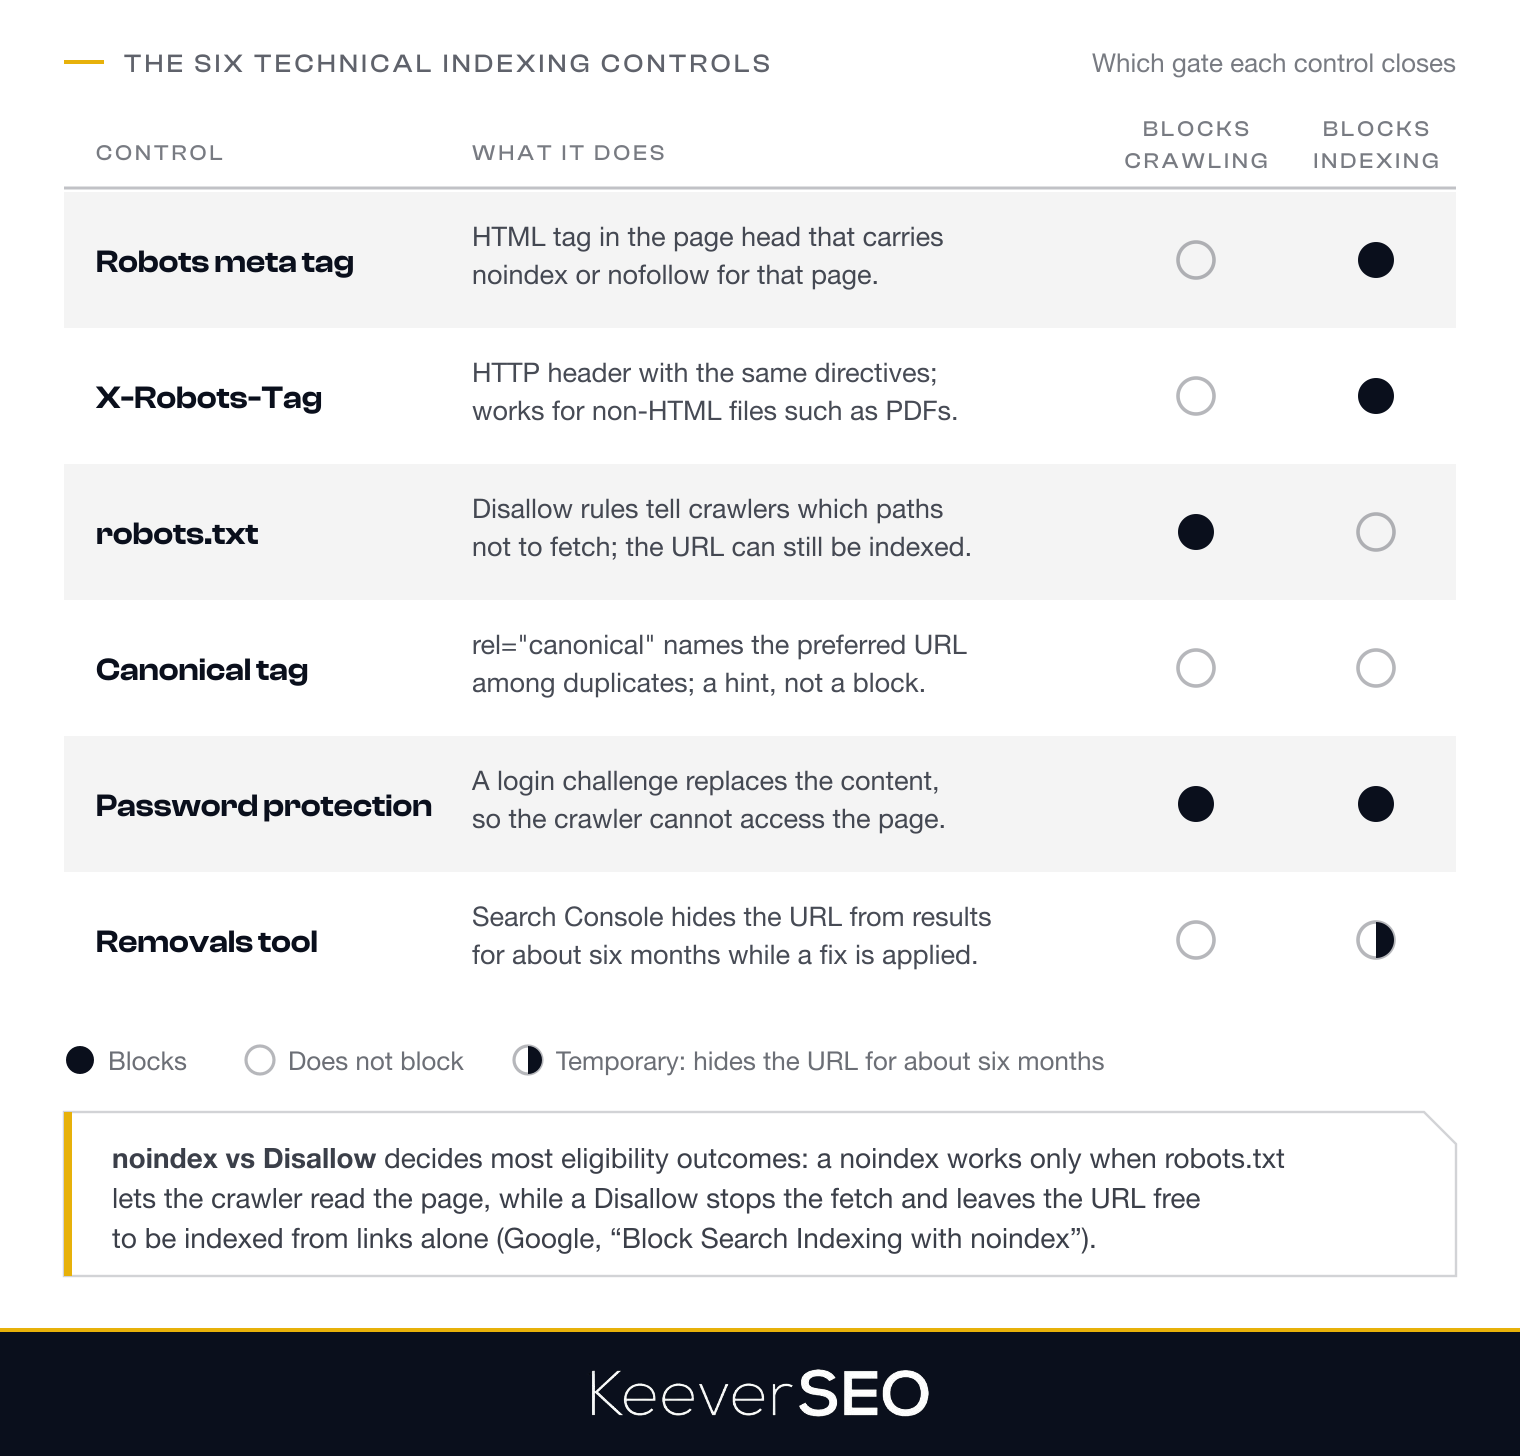
| Control | What it does | Whether it blocks crawling or indexing |
|---|---|---|
| Robots meta tag | An HTML tag in the page head that carries directives such as noindex or nofollow for that page. | Blocks indexing (with noindex); does not block crawling, and the page must remain crawlable for the directive to be read. |
| X-Robots-Tag | An HTTP response header that carries the same directives as the robots meta tag and works for non-HTML files such as PDFs and images. | Blocks indexing (with noindex); does not block crawling. |
| robots.txt | A text file at the site root whose Disallow rules tell crawlers which paths they may not fetch. | Blocks crawling only; a disallowed URL can still be indexed from links without its content. |
| Canonical tag | A rel="canonical" link element that names the preferred URL among duplicate or near-duplicate pages. | Blocks neither; it consolidates signals to the preferred URL as a hint the search engine may follow. |
| Password protection | Server-side authentication that returns a login challenge instead of the page content. | Blocks both crawling and indexing, because the crawler cannot access the content. |
| Removals tool | A Search Console tool that hides a URL from Google results for about six months. | Blocks neither permanently; it suppresses the URL from results while a lasting fix such as noindex or removal is applied. |
The distinction between noindex and Disallow decides most eligibility outcomes: Google's documentation "Block Search Indexing with noindex" states that a noindex directive works only when the page is not blocked by robots.txt and the crawler can read it, whereas a robots.txt Disallow stops the fetch and leaves the URL free to be indexed from links alone.
How do site architecture, XML sitemaps, and crawl budget affect indexing?
Site architecture, XML sitemaps, and crawl budget affect indexing by deciding which pages crawlers reach and how often. A flat architecture keeps important pages within three clicks of the homepage, which passes link signals down the hierarchy and gives crawlers short paths to every valuable URL. Deep or orphaned pages receive fewer crawler visits and wait longer for indexing.
XML sitemap hygiene keeps the sitemap limited to canonical, indexable URLs that return a 200 status code, with accurate lastmod dates and no redirected, noindexed, or duplicate entries. A clean XML sitemap tells the search engine which pages the site owner considers worth indexing and flags fresh content for recrawl.
Crawl budget is the number of URLs a crawler can and wants to fetch from a site within a given period, set by the server's crawl capacity limit and the search engine's crawl demand. Crawl budget limits which pages are reached on large sites, so parameter URLs, faceted navigation, and duplicate pages can consume the budget that valuable pages need. Crawl budget becomes a practical constraint on very large sites, above all those with more than a million unique pages or more than 10,000 pages that change daily, according to Google Search Central's "Large Site Owner's Guide to Managing Your Crawl Budget."
How do search engines index JavaScript websites?
Search engines index JavaScript websites through a render queue that executes the page's scripts before the rendered HTML is indexed. Google Search Central's "Understand JavaScript SEO Basics" documents that Googlebot processes JavaScript in three phases: crawling, rendering, and indexing. The crawler fetches the raw HTML first, queues the page for rendering, and a headless Chromium instance later executes the JavaScript to produce the final DOM. Content that appears only after JavaScript runs, such as output from AJAX calls or a single-page application (SPA), waits for the render queue before it can be indexed.
The client-side versus server-side rendering distinction decides how long that wait lasts. Client-side rendering ships a near-empty HTML shell and relies on the browser, or the render queue, to build the content, which delays indexing and risks partial indexing when scripts fail or time out. Server-side rendering (SSR) delivers the complete HTML from the server, so the crawler reads the content on the first fetch without depending on the render queue.
Dynamic rendering, which serves a pre-rendered HTML version to crawlers and the JavaScript version to users, was a workaround for sites that could not adopt SSR. Search engines now recommend SSR, static generation, or hydration approaches, because they give crawlers and users the same complete content on the first request.
How does mobile-first indexing affect the indexed version of a page?
Mobile-first indexing affects the indexed version of a page by making the mobile version the one that search engines crawl, index, and rank. Google switched the whole index to mobile-first crawling and completed the rollout in October 2023, as announced in "Mobile-first indexing has landed - thanks for all your support" on the Google Search Central Blog, so the smartphone crawler is now the primary crawler for every site. Content, structured data, and internal links that appear only on the desktop version are absent from the indexed version of the page.
Google operates two crawl types, Googlebot Smartphone and Googlebot Desktop, and mobile-first indexing means Googlebot Smartphone performs the crawl that feeds the index. Site owners must keep the mobile version complete: the same primary content, the same meta tags and structured data, the same headings, and no content hidden behind mobile-only truncation.
The practical outcome is that a page's mobile version is the indexed version, so any content missing from mobile is missing from the index. Responsive design that serves one HTML document to all devices avoids the mismatch, while separate mobile URLs or lighter mobile templates need parity checks before publication.
Why are crawled pages not indexed, and how can indexing status be checked?
Crawled pages are not indexed when the search engine judges the content too thin, duplicated, or low in value, and indexing status is checked through Google Search Console. Search Console's "Page indexing report" documentation from Google describes two non-indexed states: "Crawled – currently not indexed" and "Discovered – currently not indexed." The first state means Googlebot fetched and evaluated the page but decided against indexing it, often because of insufficient content value or duplication. The second state means Google found the URL through a sitemap or link but has not yet crawled it, often because the page is a low priority or the site faces crawl budget constraints.
Several tools verify whether a page is indexed. The site: operator in Google Search shows whether a URL is indexed when a user enters site:example.com/page-url into the search bar. Google Search Console adds the URL Inspection tool, which reports real-time index status and indexing issues for individual URLs, and the Page indexing report, which groups every site page by index status and reason for exclusion. The tools reveal whether pages are held back by technical issues or content quality, which directs the fixes. Regular monitoring through Search Console keeps valuable pages indexed and surfaces technical barriers in time.
How does indexing diagnosis support technical SEO?
Indexing diagnosis supports technical SEO by splitting every coverage problem into one of two remediation tracks: crawlability or indexability. A crawlability diagnosis asks whether the crawler can reach the URL at all, which points to robots.txt rules, server errors, broken internal links, or crawl budget waste. An indexability diagnosis asks whether a reachable page is allowed and worthy of the index, which points to noindex directives, canonical conflicts, duplicate content, and quality thresholds.
The separation drives the fix order, because a page that cannot be crawled can never be evaluated for indexing, so crawlability fixes come first and indexability fixes follow. The diagnostic value carries into a full indexing audit, whose checkpoints are laid out below.
What should an indexing audit examine?
An indexing audit should examine crawl access, index eligibility, directive conflicts, sitemap accuracy, and duplicate or thin content, in that crawlability-then-indexability order. The checkpoints are listed below:
Crawl Access Crawl access verifies that the pages that matter are reachable by search engines. The check covers server response codes, so pages return a 200 status, a review of robots.txt to confirm no valuable pages are blocked, and a scan for server timeout issues. Network connectivity and DNS resolution should be stable, and no authentication barriers should stand between the crawler and the content.
Index Eligibility Index eligibility confirms that pages intended for search visibility are not excluded. The check audits robots meta tags and X-Robots-Tag HTTP headers for noindex directives, reviews canonical tag implementations for correct references, and confirms content quality meets minimum thresholds. Unique and original content keeps pages clear of duplication issues.
Directive Conflicts Directive conflicts arise when mixed signals reach search engines. The check covers conflicts between robots.txt, meta robots tags, canonical tags, and HTTP headers, and it identifies cascading canonicalization chains that blur the primary version signal.
Sitemap Accuracy Sitemap accuracy confirms that XML sitemaps contain only canonical, indexable URLs and exclude noindexed, canonicalized, or redirected URLs. Valuable pages should be covered, and sitemaps must be formatted and submitted through Google Search Console.
Duplicate or Thin Content Duplicate or thin content review identifies pages with near-identical content across the site. Thin pages that lack substantive information are flagged, and parameterized URLs that create duplicate content are consolidated through canonicalization or redirects.
When should a business hire an SEO agency for indexing issues?
A business should hire an SEO agency when indexing problems grow too complex for internal resources to handle. The threshold is reached when indexing challenges affect large portions of a website, such as thousands of pages marked "Crawled – currently not indexed" or "Discovered – currently not indexed" in Google Search Console. Recurring coverage drops that suggest systematic problems, such as conflicting directives from noindex tags, canonical tags, or robots.txt rules, warrant professional intervention as well. A specialist SEO service provider like ours brings the expertise to diagnose and resolve the issues, restore sustainable index coverage, and prevent repeat problems. The decision to bring in an agency leads straight to the question of what gets fixed first.
What should an SEO agency fix first?
We fix crawlability problems first and indexability problems second when addressing website indexing issues. The order matters because search engine crawlers must be able to access web pages before any indexing directive or content quality signal can be evaluated. Crawlability issues involve blocked routes, server errors, or inefficient crawl paths that stop search engines from reaching or analyzing content. Once the barriers are removed, we turn to indexability and addresses noindex tags, canonical issues, and duplicate content.
Crawlability comes first because it acts as the gateway to the entire indexing process. Restoring access to every valuable URL lets us shift to indexability barriers, and the sequence prevents wasted effort because each remediation step builds on a stable foundation. Once crawlability is established, we move pages from "Discovered – currently not indexed" or "Crawled – currently not indexed" into the active index, starting with the crawlability prioritization detailed below.
How should crawlability issues be prioritized?
Crawlability issues should be prioritized by the number of valuable URLs each one blocks, starting with blocked routes such as robots.txt rules or firewall settings that shut crawlers out of whole sections. Server access problems come next, including 5xx errors, timeouts, and slow responses that cut the crawl capacity limit. Crawl budget waste, such as infinite parameter URLs, faceted navigation, and redirect chains, follows, because it drains the visits that valuable pages need. Resolved crawlability issues clear the path for the indexability prioritization that comes next.
How should indexability issues be prioritized?
Indexability issues should be prioritized by starting with directive conflicts, because an accidental noindex or a contradiction between robots meta tags, headers, and robots.txt removes pages outright. Canonicalization problems come next, since wrong or chained canonical tags hand a page's signals to the wrong URL. Content quality thresholds close the sequence, with thin and duplicate pages consolidated, expanded, or removed so the remaining pages earn their place in the index.
How should an SEO agency measure indexing improvements?
We measure indexing improvements by tracking coverage signals in Google Search Console over a horizon of weeks to months. The primary signals are the count of indexed pages, the number of URLs in each not-indexed state, and the share of valuable URLs that hold indexed status. A baseline is recorded before fixes ship, and the Page indexing report is reviewed at fixed intervals afterward, because crawl and recrawl cycles mean most shifts appear over two to eight weeks rather than days.
Organic impressions and clicks for the affected URL groups serve as secondary confirmation, since a page that enters the index should begin to earn impressions for its target queries. The measurement centers on the specific Search Console statuses that should move, which are listed below.
Which Search Console statuses should improve?
The Search Console statuses that should improve after indexing fixes are listed below:
- Crawled – currently not indexed: The count should fall as pages move into the indexed category, because pages in the state were crawled but held back for quality or duplicate content reasons.
- Discovered – currently not indexed: The count should fall as well, since the state covers URLs known to Google but not yet crawled, and improved crawlability and content quality reduce the pages left waiting.
- Indexed pages: The number of URLs in the indexed status should rise, which confirms successful indexing and eligibility to appear in search results.
The status shifts confirm that technical SEO interventions are working on both crawlability and indexability.
How should indexed URLs be compared with valuable URLs?
Indexed URLs should be compared with valuable URLs to check that the index reflects business objectives. The comparison measures the gap between the total indexed pages and the pages that carry business value, such as revenue-generating product pages or high-traffic content. A wide gap signals that low-value pages, like filters or duplicates, are consuming crawl budget and indexing resources, so the business can deindex wasteful URLs through noindex directives or canonicalization until the index holds mostly pages that contribute to business goals and search performance.
How can businesses maintain healthy index coverage?
Businesses maintain healthy index coverage through an ongoing maintenance framework rather than one-off fixes. The framework combines regular monitoring, proactive diagnosis, and prompt remediation of indexing issues. Routine technical audits confirm that crawl access stays unblocked, index directives remain free of conflicts, and XML sitemaps stay accurate and current. Monitoring for coverage drops in Google Search Console tracks shifts in indexed page counts and catches new "Crawled – currently not indexed" or "Discovered – currently not indexed" signals in good time. The discipline keeps valuable pages discoverable and eligible to appear in search results over time, whether the checks are managed in-house or through a specialist agency like SEO Agency In USA. The cadence for the checks is set out below.
How often should technical indexing checks be performed?
Technical indexing checks should be performed monthly for most sites and weekly for large or fast-changing sites, with the Page indexing report and sitemap status as the routine review points. Event-triggered reviews should follow any site migration, CMS or template change, redesign, or bulk content publication, because those events are the most common source of new directive conflicts and coverage drops. A brief check after each event catches problems before they spread across thousands of URLs.
How should new pages be monitored after publication?
New pages should be monitored after publication by submitting them through an updated XML sitemap or the URL Inspection tool's request-indexing option, then confirming index status in Search Console. The URL Inspection tool shows whether the page has been crawled and indexed and flags any blocking directive or canonical choice that diverges from the intended URL. Indexing for a new page on an established site usually lands within days to a few weeks, so a page still absent after that window warrants a crawlability and indexability review.
How should you maintain the search engine indexing mechanism?
You maintain the search engine indexing mechanism by turning diagnosis, fixes, measurement, and monitoring into one repeatable practice. The routine starts with a diagnosis that sorts every coverage problem into a crawlability or indexability track, continues with fixes applied in that order, and measures the result through Search Console statuses and the indexed-versus-valuable URL comparison. Scheduled checks and event-triggered reviews then keep the coverage stable as the site changes.
The maintenance routine closes the loop on the search engine indexing mechanism itself: search engines discover, render, parse, and store pages so they can be retrieved for queries, and a site that keeps its pages crawlable, indexable, and monitored keeps its content inside the index that every search result is drawn from.